Crawl4AI vs Maxun
Learn how Crawl4AI and Maxun differ in their key features, development activity, technology
stack and community adoption, so you can decide which of these scraping platforms & sdks is best for you.
Learn how Crawl4AI and Maxun differ in their key features, development activity, technology stack and community adoption, so you can decide which of these scraping platforms & sdks is best for you.
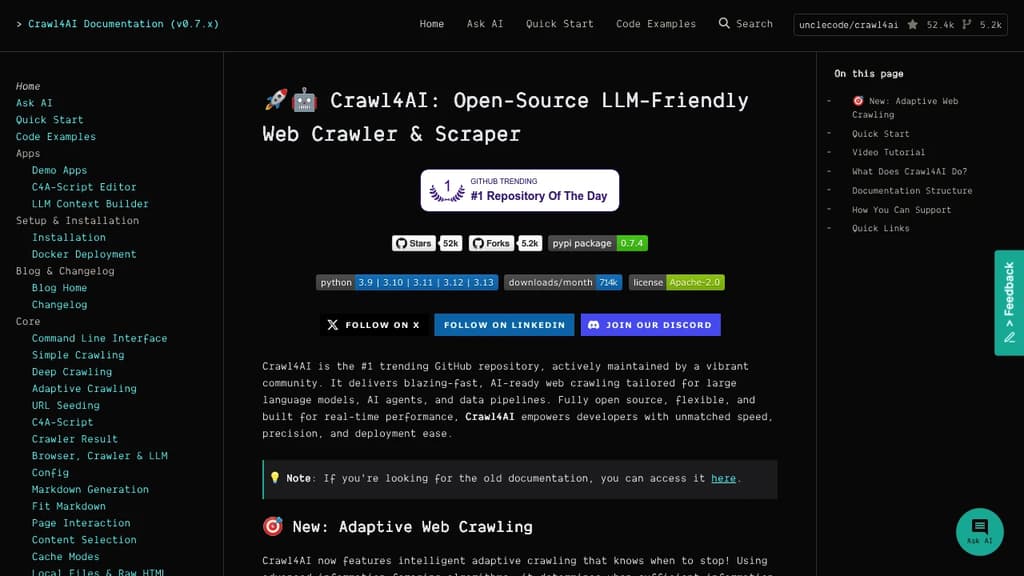
Crawl4AI
Last 30 days
Last commit
4 days agoRepository age
3 yearsVersion
v0.9.5License
Apache-2.0Self-hosted
YesRepository
unclecode/crawl4ai
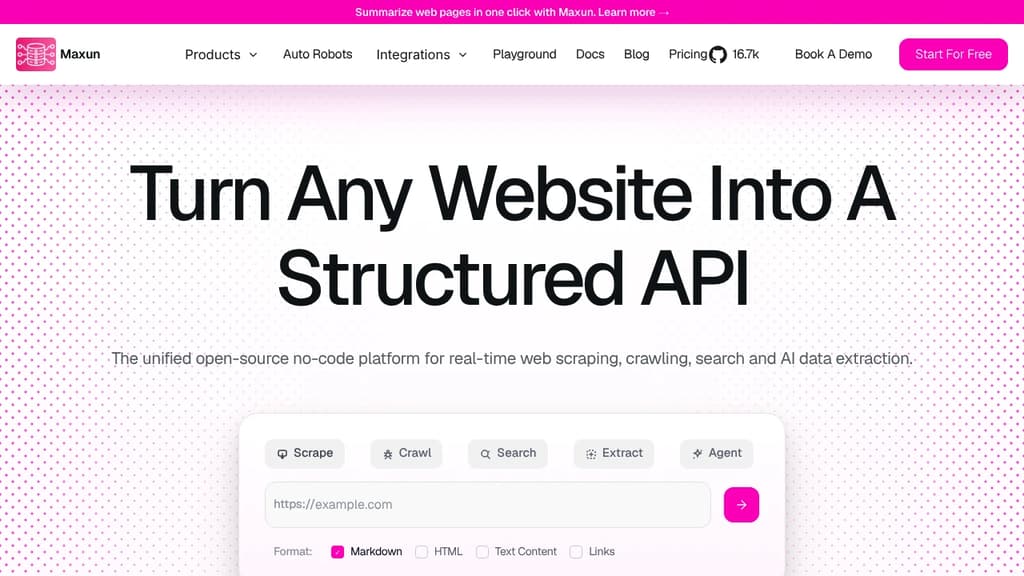
Maxun
Last 30 days
Last commit
8 hours agoRepository age
3 yearsVersion
v0.1.0License
AGPL-3.0Self-hosted
YesRepository
getmaxun/maxun
Detailed Comparison
Both Crawl4AI and Maxun have their unique strengths and serve similar purposes effectively. Consider your specific needs regarding popularity, growth, activity, technology, maturity, licensing and features when making your decision.
Both Crawl4AI and Maxun have their unique strengths and serve similar purposes effectively. Consider your specific needs regarding popularity, growth, activity, technology, maturity, licensing and features when making your decision.
Community & Popularity
Crawl4AI significantly outpaces Maxun in community adoption with 87,072 stars compared to 18,167 stars on GitHub. This 4.8x difference suggests Crawl4AI has a much larger and more active community. In terms of developer contributions, Crawl4AI has 9,072 forks, indicating strong developer engagement.
Growth Momentum
Crawl4AI and Maxun are moving at much the same rate, adding 1,988 stars and adding 443 stars respectively over the last 30 days (+2.3% vs +2.5%). Neither is pulling away from the other on momentum alone.
Development Activity
Both projects show recent activity, with Crawl4AI last updated 4 days ago and Maxun 8 hours ago.
Technology Stack
Both tools share common technology foundations, being built with JavaScript, CSS, Bash. However, they differ in their additional technology choices: Crawl4AI uses Python while Maxun leverages Typescript, JSX.
Project Maturity
Both projects started around the same time, with Crawl4AI beginning 3 years ago and Maxun 3 years ago.
Licensing
The projects use different licenses: Crawl4AI is licensed under Apache-2.0 while Maxun uses AGPL-3.0. Consider the licensing requirements when choosing for your project.
Use Cases & Features
Both tools serve similar use cases in Scraping Platforms & SDKs. However, they also have distinct specializations: Crawl4AI also focuses on Web Crawlers.
Hosting & Deployment
Both Crawl4AI and Maxun offer self-hosting capabilities, giving you full control over your data and infrastructure.

 InfluxDB – The purpose-built time series platform for high-velocity ingestion and real-time queries at scale.