Crawl4AI vs fastCRW
Learn how Crawl4AI and fastCRW differ in their key features, development activity, technology
stack and community adoption, so you can decide which of these scraping platforms & sdks is best for you.
Learn how Crawl4AI and fastCRW differ in their key features, development activity, technology stack and community adoption, so you can decide which of these scraping platforms & sdks is best for you.
Crawl4AI
Last 30 days
Last commit
4 days agoRepository age
2 yearsVersion
v0.9.5License
Apache-2.0Self-hosted
YesRepository
unclecode/crawl4ai
fastCRW
Last 30 days
Detailed Comparison
Both Crawl4AI and fastCRW have their unique strengths and serve similar purposes effectively. Consider your specific needs regarding popularity, growth, activity, maturity, licensing and features when making your decision.
Both Crawl4AI and fastCRW have their unique strengths and serve similar purposes effectively. Consider your specific needs regarding popularity, growth, activity, maturity, licensing and features when making your decision.
Community & Popularity
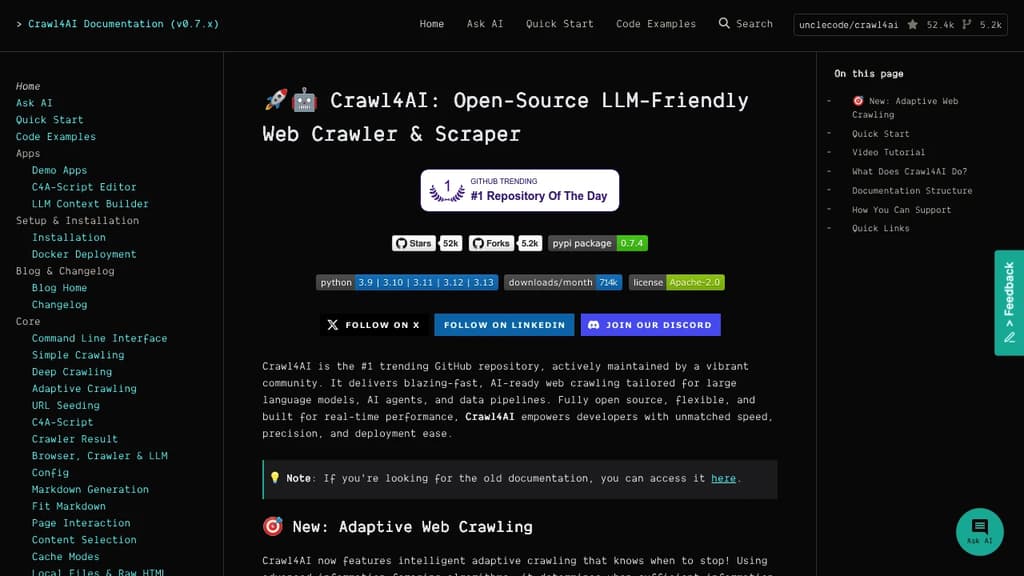
Crawl4AI significantly outpaces fastCRW in community adoption with 86,281 stars compared to 1,178 stars on GitHub. This 73.2x difference suggests Crawl4AI has a much larger and more active community. In terms of developer contributions, Crawl4AI has 8,977 forks, indicating strong developer engagement.
Growth Momentum
fastCRW is growing faster, adding 105 stars in the last 30 days (+9.8%) against adding 1,976 stars for Crawl4AI (+2.3%). fastCRW is the smaller project of the two, so it is closing the gap rather than extending a lead.
Development Activity
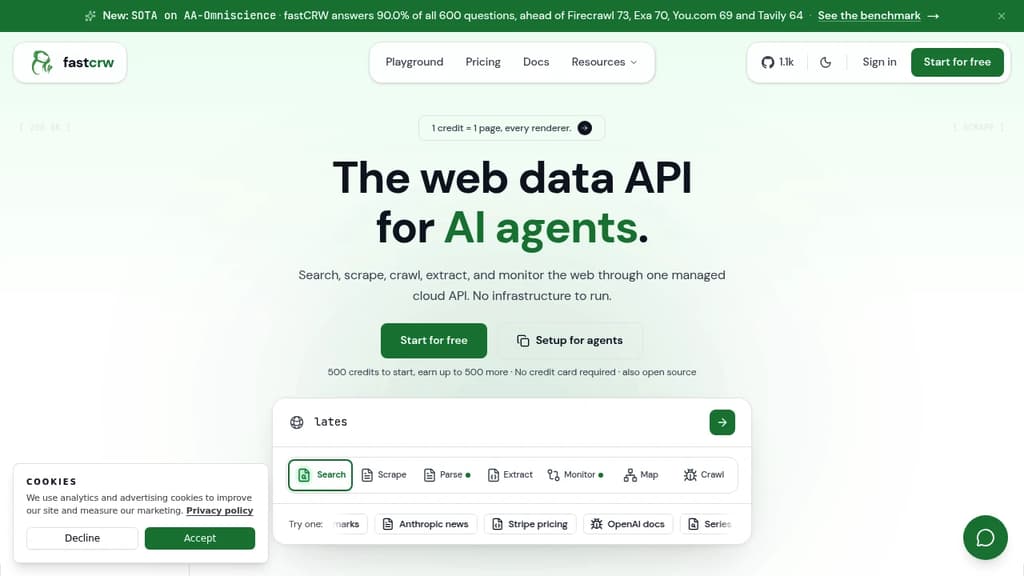
Both projects show recent activity, with Crawl4AI last updated 4 days ago and fastCRW 14 hours ago.
Project Maturity
Crawl4AI has been in development longer, starting 2 years ago, compared to fastCRW which began 8 months ago. This 1.8-year head start suggests Crawl4AI may have more mature features and established processes.
Licensing
The projects use different licenses: Crawl4AI is licensed under Apache-2.0 while fastCRW uses AGPL-3.0. Consider the licensing requirements when choosing for your project.
Use Cases & Features
Both tools serve similar use cases in Scraping Platforms & SDKs, Web Crawlers.
Hosting & Deployment
Both Crawl4AI and fastCRW offer self-hosting capabilities, giving you full control over your data and infrastructure.

 Windshift – The self-hosted platform that replaces Jira.