Open Source Last9 Alternatives
A curated collection of the 8 best open source alternatives to Last9.
The best open source alternative to Last9 is SigNoz. If that doesn't suit you, we've compiled a ranked list of other open source Last9 alternatives to help you find a suitable replacement. Other interesting open source alternatives to Last9 are: OpenObserve, VictoriaMetrics, HyperDX, and GreptimeDB.
Last9 alternatives are mainly Log Management Tools but may also be Performance Monitoring (APM) Tools or Infrastructure Monitoring Tools. Browse these if you want a narrower list of alternatives or looking for a specific functionality of Last9.

Written by Piotr Kulpinski
Comprehensive monitoring and troubleshooting solution for microservices architectures, offering metrics, traces, and logs in a single pane.
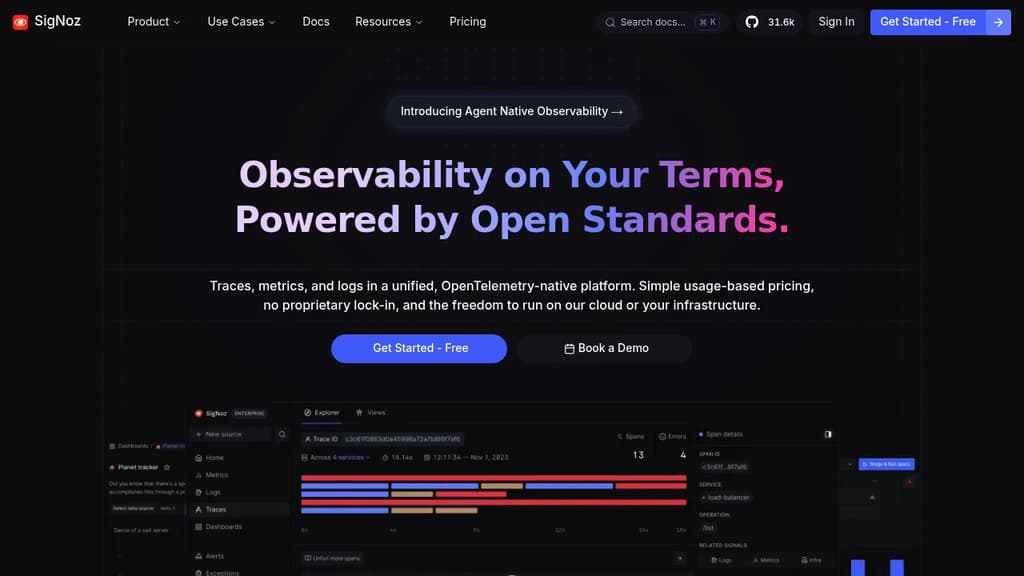
SigNoz is a powerful, open-source observability platform designed for modern, cloud-native applications. It provides a unified solution for monitoring, troubleshooting, and optimizing your microservices architecture.
Key benefits of SigNoz include:
-
All-in-One Observability: Combine metrics, traces, and logs in a single platform, eliminating the need for multiple tools and reducing context-switching.
-
Cost-Effective: As an open-source solution, SigNoz offers significant cost savings compared to proprietary alternatives, especially for high-volume data ingestion.
-
Easy Setup: Get started quickly with a simple installation process and intuitive UI, making it accessible for teams of all sizes.
-
Customizable Dashboards: Create tailored views of your system's performance with flexible, drag-and-drop dashboard builders.
-
Distributed Tracing: Gain deep insights into request flows across your microservices, helping you identify bottlenecks and optimize performance.
-
Anomaly Detection: Leverage built-in anomaly detection capabilities to proactively identify issues before they impact your users.
-
Scalability: Designed to handle high-volume data ingestion, SigNoz scales effortlessly with your growing infrastructure.
-
Open Standards: Built on OpenTelemetry, ensuring compatibility with a wide range of technologies and future-proofing your observability stack.
By choosing SigNoz, you're not just adopting a monitoring tool; you're embracing a comprehensive observability solution that grows with your needs and empowers your team to maintain high-performing, reliable applications.
Monitor logs, metrics, and traces with an open-source observability platform. Achieve petabyte scale with 140x lower storage costs and high performance.
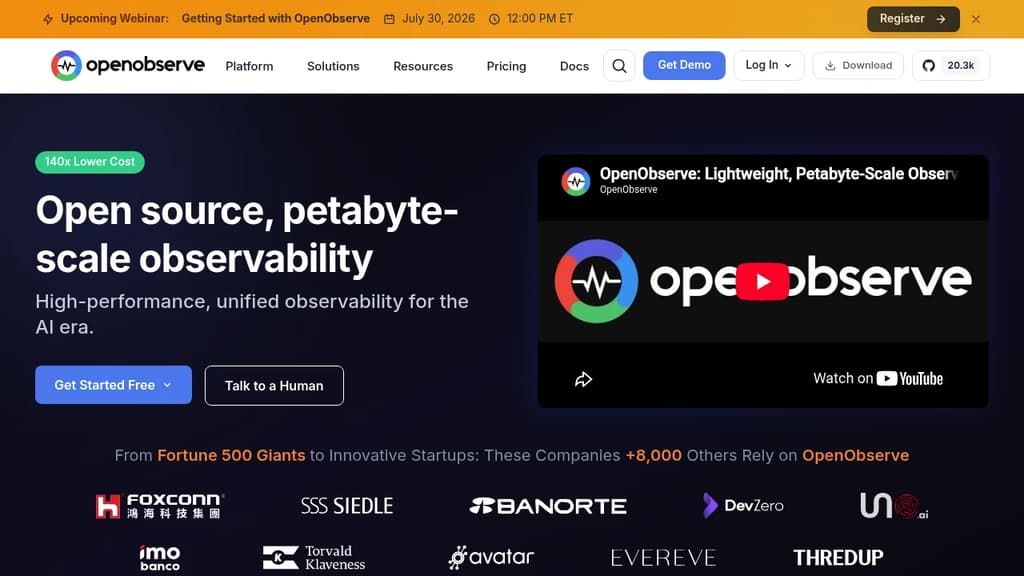
OpenObserve is a comprehensive, open-source observability platform designed for logs, metrics, and traces. It offers a modern, scalable architecture built for high performance and significant cost savings. The platform's primary advantage is its efficiency, providing up to 140x lower storage costs when compared to alternatives like Elasticsearch. This is achieved through high data compression and a columnar storage format.
Key features include:
- High Performance: Built in Rust and utilizing the DataFusion query engine for rapid data analysis, even at petabyte scale.
- Scalability: A stateless architecture allows for easy horizontal scaling to handle enterprise-level workloads.
- Cost-Effectiveness: Drastically reduces telemetry costs with high compression and the ability to use your own storage buckets like S3, GCS, and Azure Blob.
- Open Standards: Fully compatible with OpenTelemetry, ensuring seamless integration with existing tools and workflows.
Time series database and monitoring platform compatible with Prometheus, handling billions of metrics with lower resource usage than most alternatives.
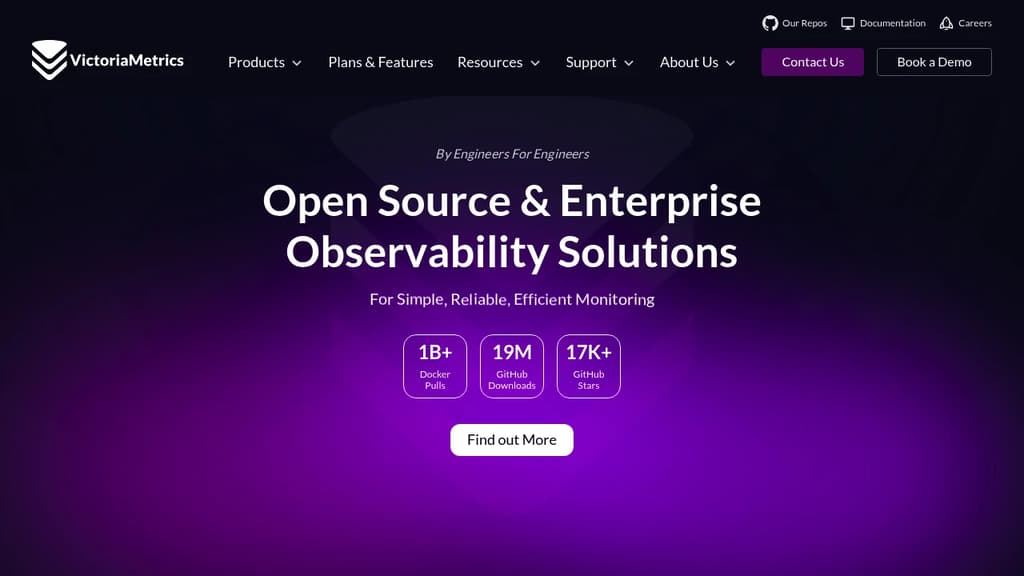
VictoriaMetrics is a time series database and observability platform built for teams that need to store and query large volumes of metrics, logs, and traces without the cost and complexity that typically comes with scale. It works as a drop-in replacement for Prometheus, so existing queries, dashboards in Grafana, and scrape configs carry over without rewriting anything.
The core appeal is efficiency. Organizations routinely report 5x to 10x reductions in storage and compute costs compared to Prometheus, Mimir, or InfluxDB at equivalent workloads. It handles millions of metrics per second on modest hardware, which makes it practical anywhere from a Raspberry Pi home lab to thousand-core distributed clusters.
Key capabilities include:
- MetricsQL: an extended query language compatible with PromQL, with additional functions for common monitoring patterns
- Long-term retention: store metrics for months or years rather than days, with optional downsampling in the enterprise tier
- High cardinality handling: stays performant where Prometheus struggles under large numbers of active time series
- OpenTelemetry support: ingest traces and logs alongside metrics through a unified stack
- Horizontal scalability: a cluster mode distributes ingestion and storage across nodes for very high throughput
- Single-binary simplicity: the single-node version runs as one process with no external dependencies
VictoriaMetrics competes directly with tools like OpenObserve, HyperDX, and GreptimeDB in the open source observability space. Its strongest differentiator is the combination of Prometheus compatibility and genuine resource efficiency at scale. Teams already running Prometheus can migrate incrementally, often within minutes, without touching their alerting rules or existing instrumentation.
An enterprise tier adds multi-tenancy, anomaly detection, downsampling, and dedicated engineering support. The open source version covers the full core feature set with no artificial limits on retention or ingestion rate.

Open source observability platform unifying session replays, logs, traces, metrics and errors. Fast search, automatic clustering, $0.40/GB pricing.
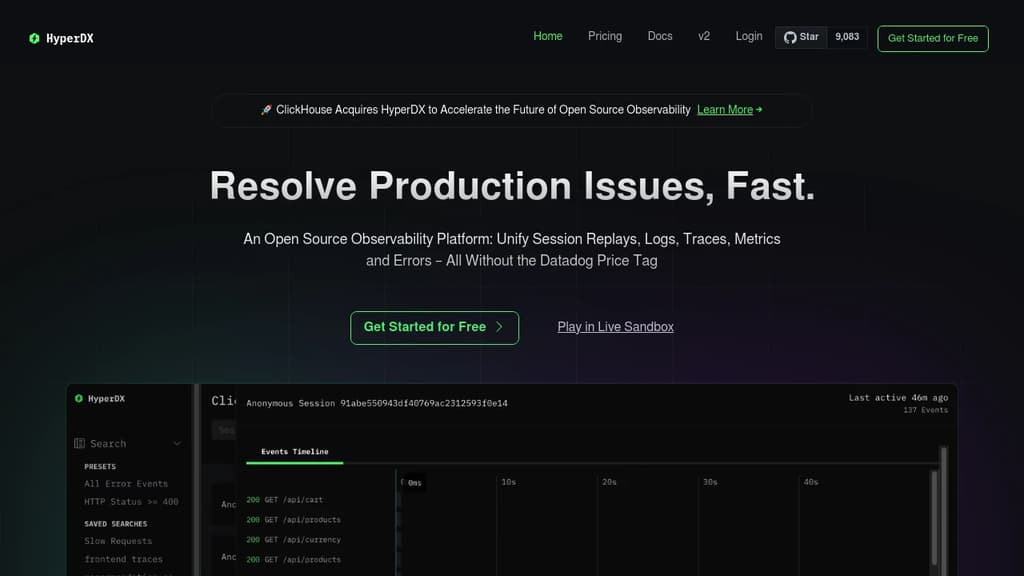
Open source observability platform that unifies session replays, logs, traces, metrics and errors into a single view - all without the expensive Datadog price tag. Recently acquired by ClickHouse to accelerate open source observability innovation.
Key capabilities include:
- End-to-end correlation - Trace requests from user browsers to backend servers and async workers automatically
- Blazing fast search - Query terabytes of events in seconds, powered by ClickHouse
- Automatic clustering - Condense billions of events into distinctive patterns without manual configuration
- Session replay integration - Automatically link user sessions with backend logs and traces
- Intuitive visualization - Build charts and graphs with simple full-text search, no complex syntax required
Developer-friendly features:
- OpenTelemetry-powered instrumentation prevents vendor lock-in
- Agent-free installation option eliminates infrastructure overhead
- Native JSON parsing for structured logs with zero configuration
- Real-time live tail for immediate log stream monitoring
- Intercom integration for jumping directly from support tickets to user sessions
Transparent pricing at $0.40 per GB with no per-user or per-host fees makes enterprise-grade observability accessible to teams of all sizes. Trusted by high-velocity engineering teams for resolving production issues fast.
Cloud-native observability database unifying metrics, logs, and traces with sub-second queries, 50x cost reduction, and seamless OpenTelemetry integration.
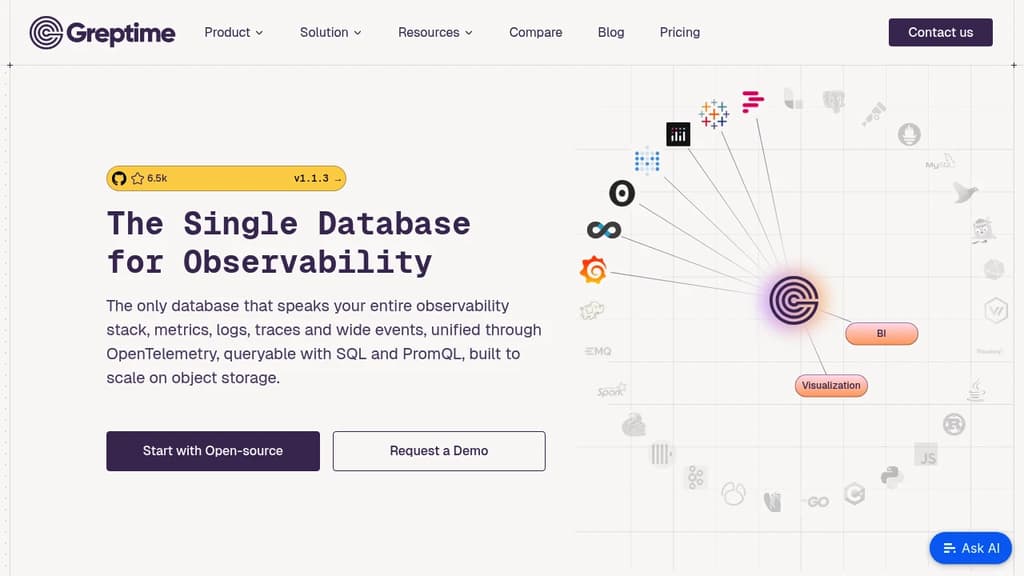
GreptimeDB is a cloud-native, real-time observability database that revolutionizes how organizations handle metrics, logs, and traces. Built for OpenTelemetry and modern cloud environments, it delivers sub-second query performance at petabyte scale while dramatically reducing operational complexity.
Key benefits include:
- All-in-One Solution: Process metrics, logs, and traces through a unified database with full SQL, PromQL, and streaming processing support
- Exceptional Performance: Built with Rust for reliability, featuring rich indexing options (inverted, fulltext, skipping, and vector) that enable sub-second responses on massive datasets
- Massive Cost Savings: Achieve 50x lower operational and storage costs through compute-storage separation and flexible cloud scaling
- Infinite Scalability: Purpose-built for Kubernetes with industry-leading architecture that handles cardinality explosion at massive scale
- Developer-Friendly: Access through standardized interfaces including web dashboard, REST API, and MySQL/PostgreSQL protocols
- Flexible Deployment: Deploy anywhere from ARM-based edge devices to cloud environments with unified APIs
Trusted by companies like Li Auto (reduced traffic costs by 50%, storage costs by 98%), SGCC (2x write performance, 5x query performance), and others who have migrated from InfluxDB, Loki, and Thanos to achieve superior performance and simplified operations.

Uptrace is an OpenTelemetry-based platform that integrates traces, metrics, and logs to help monitor and optimize complex distributed systems.
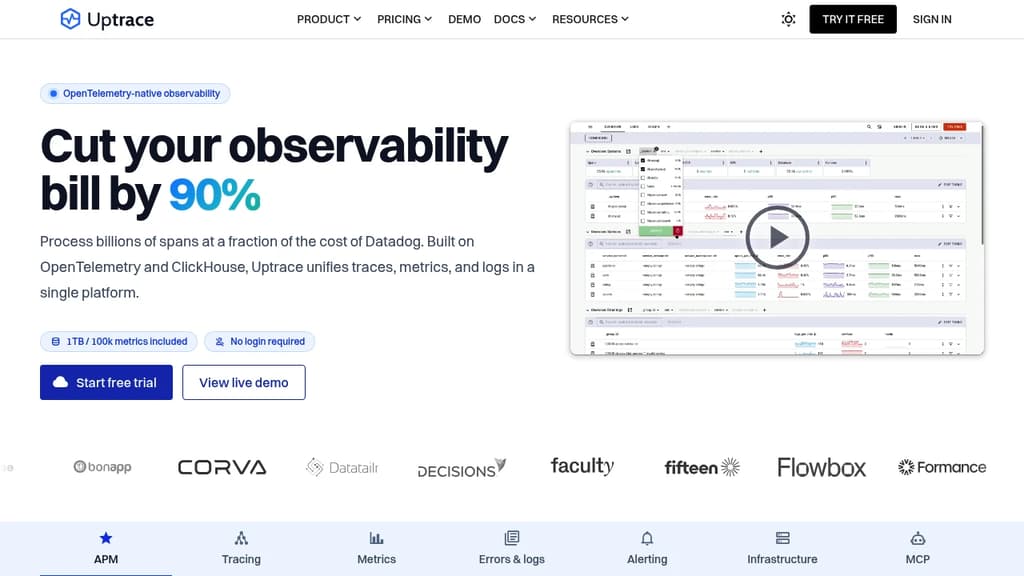
Uptrace is an open-source observability platform built on OpenTelemetry, designed to help developers and operations teams monitor, understand, and optimize complex distributed systems. It offers a comprehensive solution for application performance monitoring (APM) with integrated tracing, metrics, and logging capabilities.
Key features and benefits:
-
All-in-one solution:
- Integrates traces, metrics, and logs in a single platform
- Eliminates the need for multiple monitoring tools
- Supports data from OpenTelemetry, Prometheus, Vector, FluentBit, and CloudWatch
-
Flexible deployment options:
- Self-hosted: Free to use without limitations
- Managed cloud service: For those who prefer a hands-off approach
- On-premise installation available upon request
-
Cost-effective and predictable pricing:
- Pay only for ingested gigabytes and active timeseries
- Set a budget to avoid unexpected costs
- First month free with 1TB storage and 50,000 timeseries (no credit card required)
-
OpenTelemetry integration:
- Quick setup with minimal code changes
- Supports multiple programming languages (Go, Python, Ruby, Node.js, .NET, Java, Erlang, Elixir, Rust, PHP)
- Vendor-agnostic instrumentation for easy switching between providers
-
Comprehensive monitoring dashboard:
- Service graph showing relationships between components
- RED metrics (Rate, Errors, Duration)
- Latency percentiles (p50/p90/p99/max)
- Most frequent logs and errors
- Slowest requests identification
-
Scalability:
- Designed to work at any scale, from small applications to large distributed systems
-
Incident response:
- Helps teams identify and resolve issues quickly, often before customers notice
By offering a unified platform for observability, Uptrace simplifies the monitoring process and provides valuable insights into application performance, helping teams optimize their systems and respond to incidents more effectively.
Observability platform built on OpenTelemetry and ClickHouse. Collect, visualize, and query distributed traces, logs, and metrics, with an MCP server for AI agent diagnostics.
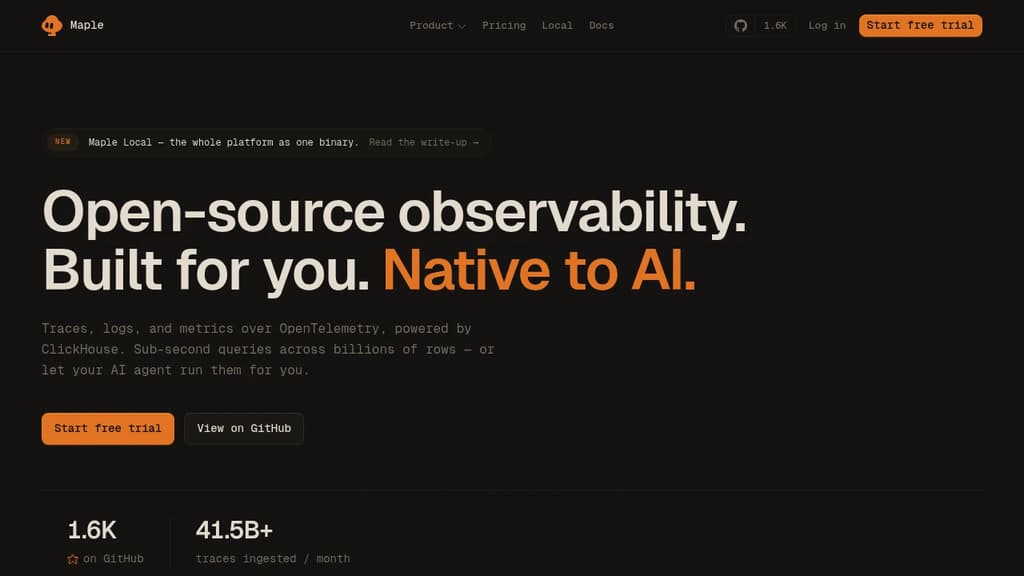
Maple is an observability platform for distributed systems, built on OpenTelemetry and backed by ClickHouse for sub-second queries across billions of rows. It handles traces, logs, and metrics in one place, with correlated data across all three signals tied to a single trace ID. No stitching between tools, no second search in a second product.
The incident workflow is its sharpest edge. An alert arrives carrying the service, the broken threshold, and sample traces. From there you open the failing span tree, jump to correlated logs on the same trace ID, and see exactly what happened. Retry exhaustion, a full connection pool, three Stripe timeouts at 1.75 seconds each – all visible without switching tabs.
Key capabilities:
- Distributed tracing – full span trees with every attribute intact, no sampling gap hiding the outlier
- Structured logs – OTLP logs searchable by severity, service, message, and duration in seconds
- Session replay – browser clicks, routes, console lines, and failed requests, joined to spans by session ID
- Metrics and dashboards – request rate, error rate, latency percentiles, drag-to-build or agent-suggested
- Service maps – live request flow across services, the dependency cascade you'd otherwise reconstruct after the fact
- Error tracking – errors grouped by type, with trends, affected services, and sample traces attached
- Alerting – seven signal types with severity, incident tracking, and auto-resolution; routes to Slack, Discord, PagerDuty, or any webhook
- MCP server – any compatible AI agent (Claude, Cursor, others) can list services, search traces, read source files, and open a PR with a proposed fix
- Kubernetes integration – Helm chart that joins spans to pod, node, and namespace; kube-state metrics included
Compared to tools like HyperDX or Uptrace, Maple's first-class MCP surface is a genuine differentiator. The agent doesn't just read dashboards – it pulls the source file behind a failing span, so the fix it proposes cites your actual code. It can also write back: claim an issue, set severity, attach a fix.
The local mode runs as a single compiled binary with an embedded ClickHouse, OTLP ingest, query API, and dashboard – all on localhost, no account required. For production, you can self-host against your own ClickHouse or use the hosted plan at $39/month for 100 GB per signal, then $0.30/GB flat. No per-host fees. No per-seat fees.
The source is on GitHub under FSL-1.1, which converts to Apache 2.0 two years after each release. OpenTelemetry in means no proprietary agent and no re-instrumentation if you switch.
Unified platform for logs, metrics, traces and profiles with native compatibility for popular tools like OpenTelemetry, Prometheus, and Loki. No data silos, no usage limits.
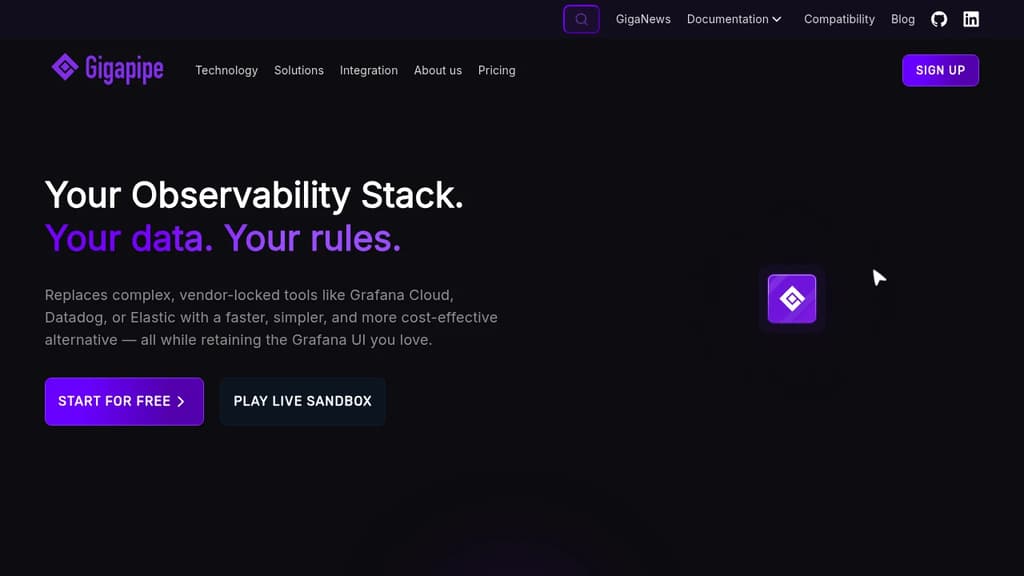
A powerful observability platform that brings together logs, metrics, traces and profiles in one unified solution. Built on high-performance OLAP engines ClickHouse and DuckDB with NVMe storage, Gigapipe delivers exceptional speed and reliability.
Key advantages:
- Drop-in compatibility with OpenTelemetry, Loki, Prometheus, Tempo, Pyroscope and other popular tools
- Flat-cost pricing model with no usage limits or surprise bills
- True open source solution under AGPLv3 license
- Single platform approach eliminates data silos and reduces complexity
- Native support for thousands of compatible agents
- Query API that emulates familiar tools like Loki and Prometheus
Perfect for engineering teams and DevOps professionals who need comprehensive observability without the complexity of managing multiple tools or worrying about data volume costs. Gigapipe's polyglot approach ensures you can work with your data your way, while the unified platform enables quick correlation between different data types for faster troubleshooting and deeper insights.

People are looking for alternatives to...
View all alternatives
Claude Code
Spotify
Notion
CapCut
Lovable
Wispr Flow
 Stellar Hosted – Managed Open Source software hosting in the EU: secure, compliant, fast.
 Sent