Open Source Kortix Alternatives
A curated collection of the 8 best open source alternatives to Kortix.
The best open source alternative to Kortix is Hermes Agent. If that doesn't suit you, we've compiled a ranked list of other open source Kortix alternatives to help you find a suitable replacement. Other interesting open source alternatives to Kortix are: AutoGPT, LobeChat, nanobot, and ZeroClaw.
Kortix alternatives are mainly AI Agent Platforms but may also be AI Personal Assistants or AI Chat Interfaces. Browse these if you want a narrower list of alternatives or looking for a specific functionality of Kortix.

Written by Piotr Kulpinski
Cross-platform desktop agent from Nous Research that connects to Telegram, Discord, Slack, WhatsApp, and more, with persistent memory, scheduling, and isolated sandboxing.
Hermes Agent is a desktop AI agent built by Nous Research that runs natively on macOS, Windows, and Linux. It's designed for people who want a single agent that works across their communication tools, handles recurring tasks, and actually remembers what it's done before.
The core idea is persistence. Most agents start fresh every session. Hermes maintains memory across conversations, auto-generates skills from past interactions, and builds up context about your projects over time. You don't have to re-explain things.
Where it connects:
- Telegram, Discord, Slack, WhatsApp, Signal, and email are all supported natively, so the agent meets you where you already work
- A CLI interface is also available for terminal-first workflows
What it can do:
- Natural-language scheduling for reports, backups, and briefings that run unattended
- Web search and browser automation with vision, image generation, and text-to-speech
- Subagents that run in isolated conversations with their own terminals and Python RPC scripts, useful for parallel pipelines without ballooning context costs
- Multi-model reasoning with access to 300+ models through the Nous Portal
Sandboxing is a genuine differentiator. Five execution backends (local, Docker, SSH, Singularity, and Modal) give you control over where code actually runs, with container hardening and namespace isolation. That matters if you're running automated tasks or untrusted scripts.
For teams or individuals already using LobeChat or similar multi-surface chat interfaces, Hermes takes a different angle: it's less about chat UI and more about an agent that operates autonomously across surfaces. Think of it as closer to an AgentOS approach, where the agent itself is the persistent layer.
It's free to use under the MIT license, with paid tiers through the Nous Portal for higher model access and monthly credits.
Platform for building, deploying, and running AI agents that automate repeatable digital work across research, outreach, content, and support without writing code.
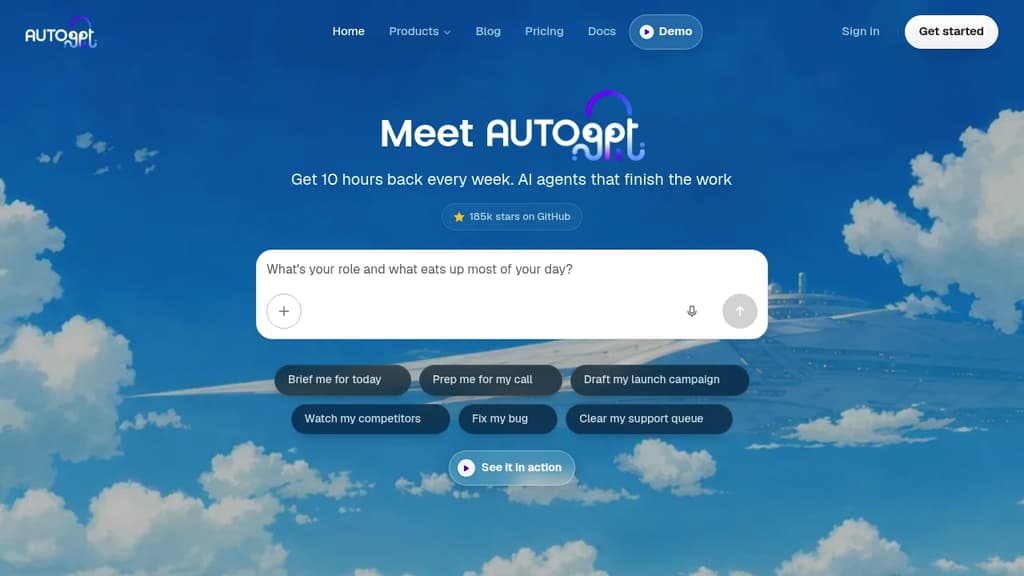
AutoGPT is an AI agent platform for people who want to hand off recurring work entirely, not just get help with a single task. You describe the outcome you want, and an agent plans and executes every step: pulling data, calling AI models, updating spreadsheets, sending messages, and looping back on a schedule. It's built for the kind of work that comes back every day or every week.
There are four ways to interact with the platform:
- AutoPilot lets you describe a job in plain English and builds the agent for you inside the conversation, no flowcharts or prompt engineering required.
- Visual Builder gives you a drag-and-drop canvas of blocks when you need exact control over branching, looping, and routing logic.
- Dashboard shows every agent's status, run history, and spend in one place, with alerts when an agent needs a decision from you.
- Marketplace offers ready-made agents from AutoGPT and the community, browsable without an account and deployable in one click.
On the integration side, the platform ships with dozens of AI models already connected (no API keys needed) and supports services like Gmail, Slack, Google Sheets, Notion, HubSpot, GitHub, and Airtable. Agents can handle chat, image generation, video, transcription, OCR, and more across 45+ platforms.
Common uses include morning briefings assembled from earnings and headlines, prospect research before sales calls, overnight campaign drafts, support ticket triage, and competitor monitoring that only pings you when something actually changes.
AutoGPT is fully open source. Self-hosting is free: you bring your own model API keys and infrastructure and get the same builder and agent runtime as the cloud. The hosted cloud removes the ops burden and covers model usage through a subscription. Teams often prototype in the cloud and move sensitive workloads on-prem later.
For teams that want a visual workflow automation approach rather than agent-based logic, tools like ByteChef or Automa take a different angle. If you're looking for an agent-first experience with a different focus, Eigent is worth comparing. AutoGPT's sweet spot is repeatable, multi-step work you can describe clearly enough to hand to a capable assistant.
A collaborative platform to create, schedule, and operate AI agents that handle long-running tasks, team workflows, and automated jobs without constant oversight.
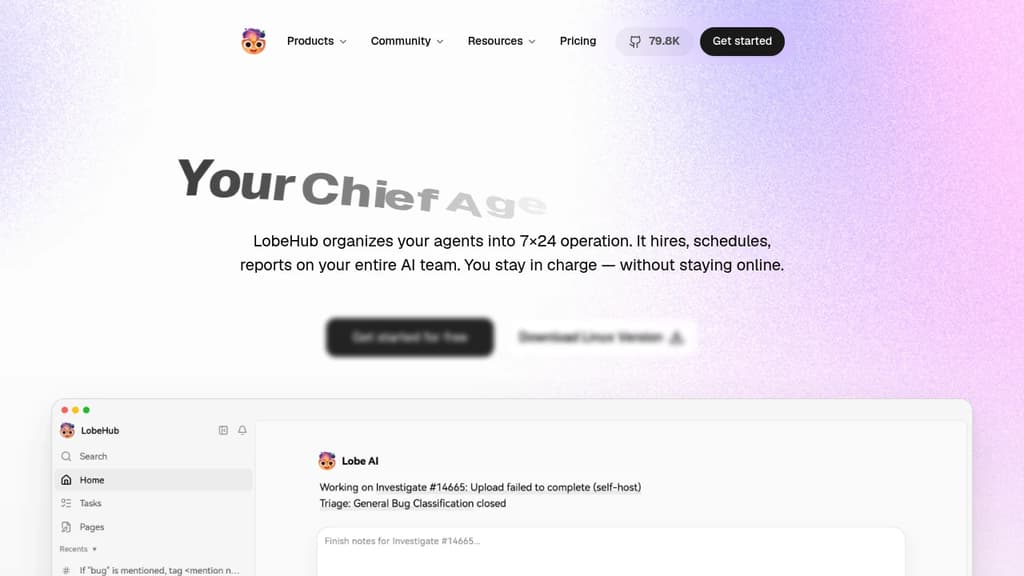
LobeHub is a platform for building and operating teams of AI agents. Rather than managing individual AI tools one at a time, it lets you assemble agents into coordinated groups, assign them tasks, and let them run. Agents report back on progress while you focus on higher-level decisions.
The agent builder starts from a single sentence. From that, LobeHub automatically configures names, roles, skills, and behaviors. Agents connect to a library of over 312,000 skills, and you can attach any model or modality you want. It works with providers like OpenAI and Anthropic, so you're not locked into one AI backend.
For longer or more complex work, LobeHub supports agent groups that self-assemble based on the task at hand. Multiple agents can work in parallel, iterate on each other's output, and handle multi-step jobs. This matters most for things like large-scale issue triage, content workflows, or anything that would otherwise require constant human coordination. Among AI agent platforms, that kind of parallel execution is still relatively rare.
The platform includes several workspace-style features: Pages for writing and refining documents with multiple agents sharing context, Projects for organizing work, Schedules for time-based task automation, and a shared Workspace with visibility controls for teams. There's also an IM Gateway that connects agents to messaging platforms where your team already communicates.
Agents are designed to improve over time. Personal Memory builds a structured, editable model of how you work. Continual Learning adjusts agent behavior based on patterns it observes. Memory is white-box, meaning you can inspect and edit what the system knows about you rather than treating it as a black box. That's a meaningful difference from tools like Khoj, where memory handling is less transparent.
LobeHub is open source and has a community component where agents and skills can be shared. It's built for individuals and teams who want AI to handle ongoing, multi-step work rather than single-turn interactions. If you're already using a knowledge management platform like Pipeshub or a multi-agent framework like Agno, LobeHub sits closer to the operational end of that spectrum, focused on running work rather than just organizing it.
Lightweight, self-hosted AI agent that runs in a web UI, terminal, or chat app, handling long-running workflows with controlled token budgets.
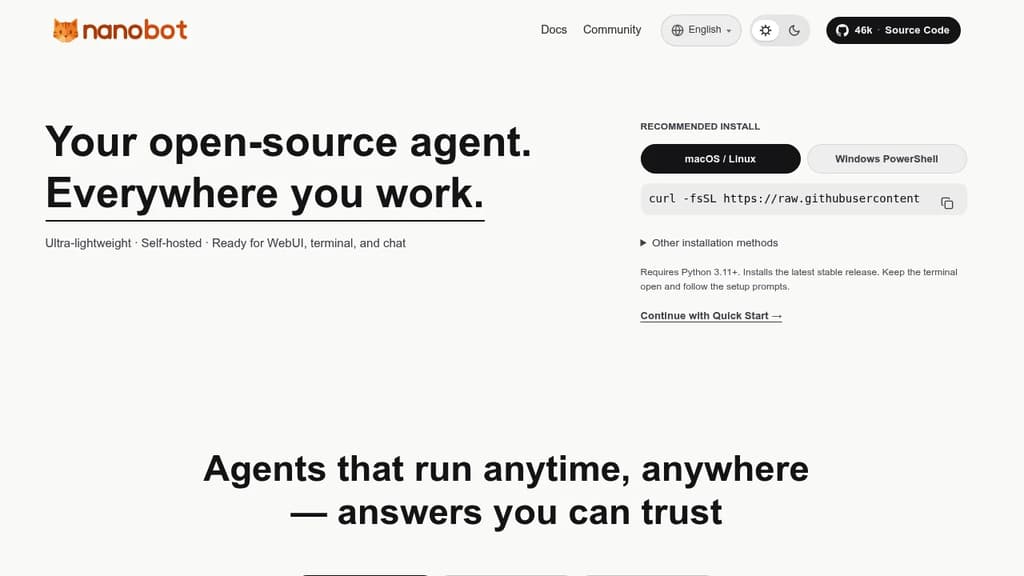
nanobot is a minimal, self-hosted AI agent designed to run wherever you work: a web UI, your terminal, or a chat interface. It's built for people who want a personal AI agent they control, without the overhead of bloated frameworks or cloud-locked platforms.
The core design philosophy is lean execution. Rather than consuming tokens without restraint, nanobot applies sensible context management and explicit token budgets, so your costs stay predictable. That matters especially for long-horizon tasks, where the agent needs to sustain coherent reasoning across tens or even hundreds of steps without losing the thread.
Key capabilities:
- Multi-surface operation: runs in a browser-based web UI, a terminal, or directly inside chat apps, so you're not locked into one interface
- Long-running workflows: maintains steady execution across complex, multi-step tasks without context drift
- Token budgeting: built-in controls keep spending predictable, unlike agents that leave cost management entirely to the user
- Embeddable runtime kernel: the agent core is portable, so you can drop it into a business workflow or a personal automation setup without rewiring everything around it
- Self-hosted: your data stays on your infrastructure; no third-party service holds your conversations or task history
Compared to heavier agent frameworks or fully managed platforms like Agenta, nanobot stays deliberately small. The codebase is compact, the runtime is portable, and the architecture doesn't assume you want a full orchestration platform. It suits developers and technically minded individuals who want an agent they can embed, extend, or just run locally without a lot of ceremony.
It supports automation tasks, developer integrations, and conversational use cases through the same core runtime. The MIT license means you can adapt it freely for personal or commercial use.
A single Rust binary that runs a personal AI agent on your own hardware, connecting to 70+ LLM providers and 30+ messaging channels with built-in sandboxing and cryptographic tool receipts.
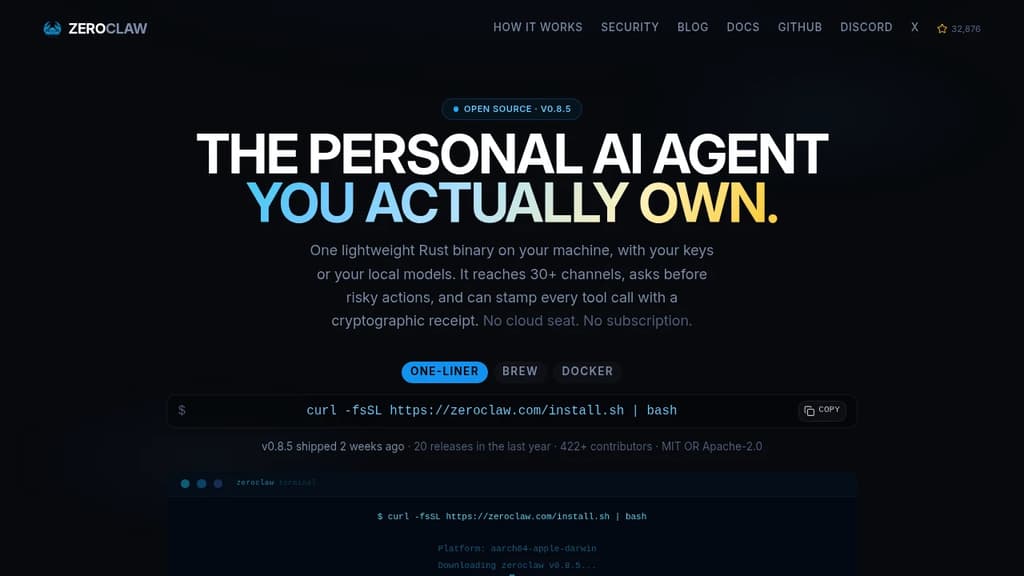
Most AI assistants are a seat you rent on someone else's infrastructure. ZeroClaw runs as a single native binary on your own machine, using your own API keys or fully local models like Ollama. No cloud seat, no subscription, no ZeroClaw server in the middle.
The binary is built in Rust and starts in under 20ms. It uses less memory than a browser tab and runs on everything from a workstation to a Raspberry Pi, including ARM and x86. There's no Node, JVM, or Python environment to install.
What it connects to:
- 70+ LLM providers: local options like LM Studio, llama.cpp, vLLM, and LocalAI, plus hosted providers including Anthropic, OpenAI, Google Gemini, Amazon Bedrock, Mistral, Groq, and any OpenAI-compatible endpoint
- 30+ channels: Telegram, Discord, WhatsApp, Slack, Signal, iMessage, Matrix, email, IRC, Bluesky, Reddit, Nostr, Notion, webhooks, and more
- Hardware: GPIO on Raspberry Pi, STM32, Arduino, and ESP32
Security is the default posture, not an add-on.
- Supervised autonomy: medium-risk actions require your approval before they run; high-risk ones are blocked outright
- OS-level sandboxes: Landlock, Bubblewrap, Seatbelt, or Docker contain what the agent can touch, enforced by the kernel rather than a prompt
- Command allowlists: explicit workspace scoping decides what runs and where
- Tool receipts: every successful tool call can be stamped with an HMAC-SHA256 tag the model cannot forge, making fabricated runs or invented results detectable
YOLO mode exists for trusted dev environments and is strictly opt-in.
The agent supports multiple named agents running from a single daemon, each isolated. Skills package repeatable tasks with their tools. Scheduled jobs, webhook triggers, and channel events all run through the same agent loop inside the same sandbox and allowlists you've scoped. A2A discovery lets agents describe and find one another through the gateway.
With a local model, nothing leaves your machine at all. With a hosted provider, only your prompts go to the provider you chose, using your own key. Dual-licensed MIT OR Apache-2.0.
Collection of open blueprints combining models, agent harnesses, and runtime controls to deploy specialized autonomous AI agents with policy-based guardrails.
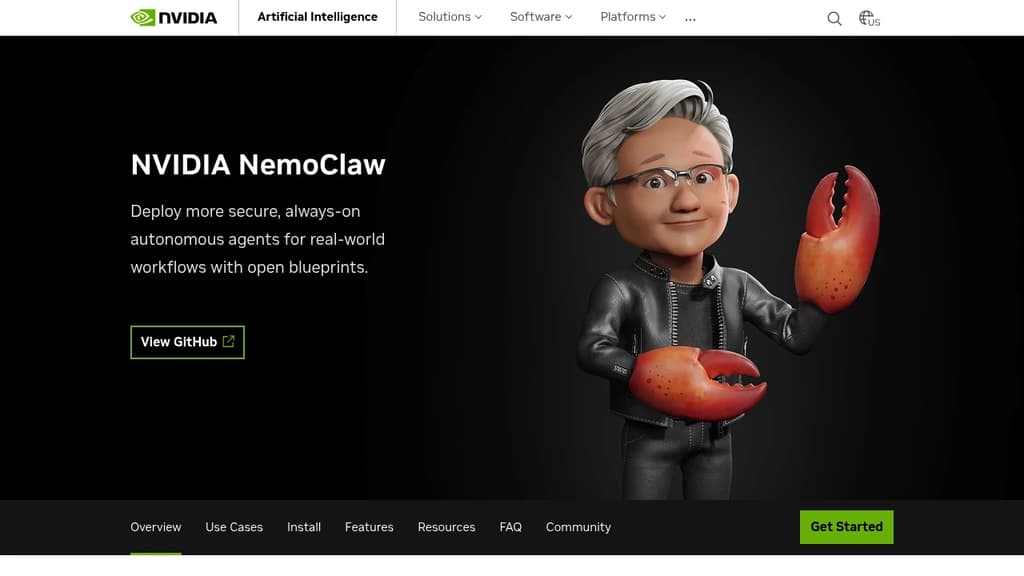
NVIDIA NemoClaw is a collection of open blueprints for building and deploying autonomous AI agents. It's aimed at teams that have moved past the prototype stage and need to run always-on, domain-specialized agents in real workflows with actual governance controls, not just a demo that works in a sandbox.
At its core, NemoClaw bundles three things together: a model (open or frontier), an agent harness, and a runtime. The runtime is OpenShell, which enforces what the agent can actually touch, files, networks, credentials, and tools. That separation matters. You get agents that can reason and act autonomously without giving them unchecked access to your systems.
The blueprints support several agent harnesses:
- OpenClaw agents get OpenShell policy controls, lifecycle management, and sandboxing layered on top, moving them from open-ended prototypes to governed deployments.
- LangChain Deep Agents are tuned for Nemotron 3 Ultra, with benchmark-leading accuracy among open models and the flexibility to swap in other models.
- Hermes agents from Nous Research use a skills-and-memory loop, letting agents learn from experience and reuse successful workflows while staying within defined privacy and inference guardrails.
Model choice is flexible. You can run local open models, route to cloud-based frontier models, or use a model router that picks between them based on your privacy and performance policies. That makes NemoClaw practical for organizations that can't send everything to an external API.
Real-world use cases already documented include chip design verification (Cadence cut RTL verification from weeks to hours), product manufacturing automation, and controlling tools like Blender and NVIDIA Omniverse from within governed sandboxes. These aren't toy examples.
For teams building agentic pipelines or comparing against other agent orchestration approaches, NemoClaw's distinguishing angle is the combination of open blueprints with enforced runtime policy. The agent harness handles what the agent does; OpenShell handles what it's allowed to do. That boundary is explicit and configurable, not just a best-practice suggestion.
NVIDIA also contributes directly to the OpenClaw project and partners with harness developers like LangChain and Nous Research, so the blueprints stay current with upstream changes.
Autonomous AI agent framework that operates on its own sandboxed computer, creates tools dynamically, manages memory, and executes multi-step workflows with full transparency.
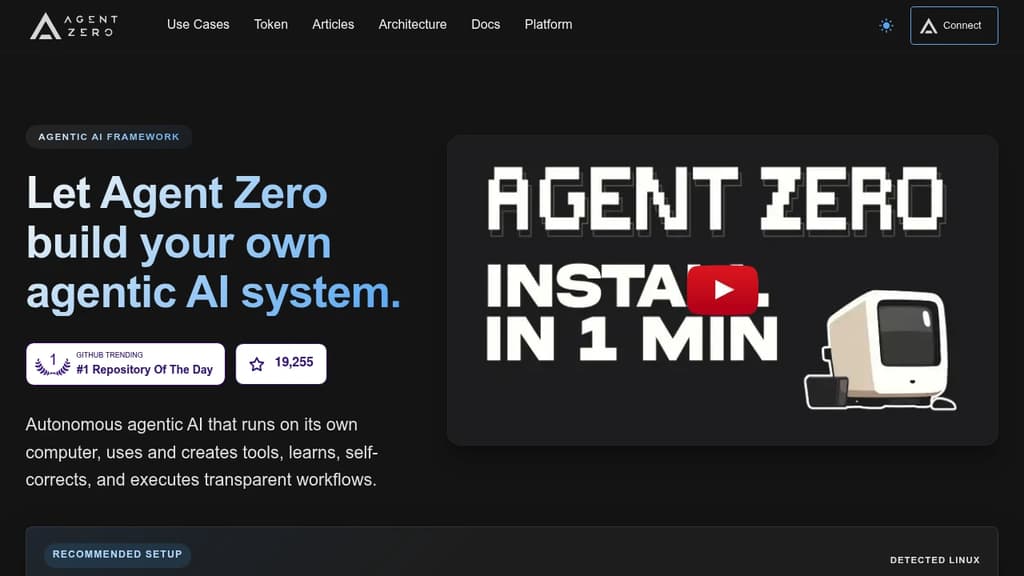
Agent Zero is an agentic AI framework built for people who want autonomous AI that actually does work, not just answers questions. It runs inside a sandboxed Docker environment with its own terminal, file system, and browser, so agents can execute real tasks end-to-end without touching your local machine unless you explicitly connect them.
The core idea is that agents shouldn't need pre-built tools for every situation. Agent Zero creates tools on the fly as tasks demand them, learns from past runs, and self-corrects when something goes wrong. Workflows are fully transparent: you can see what the agent is doing, why, and what it's executing at every step.
Key capabilities:
- Multi-provider support: Connect any LLM provider without exposing API keys to the agent itself.
- Dynamic tool creation: Agents write and reuse tools as needed rather than relying on a fixed library.
- Agentic memory and RAG: Persistent knowledge management lets agents recall context across sessions and build on prior work.
- Subordinate agents: Spawn specialized sub-agents to handle parallel or delegated tasks within a single workflow.
- Plugin Hub: Browse, install, and update community plugins directly from the UI, with built-in AI-driven security scanning before deployment.
- A0 CLI Connector: Bridge the sandboxed agent to your local terminal and project files when you need it.
- Context engineering: Prompt structure is tuned to stay efficient on local models and scale to larger ones without bloat.
Agent Zero suits developers and power users who want a self-hostable AI personal assistant they can extend, audit, and fully control. Unlike closed systems such as ChatGPT or Manus, every layer is inspectable and modifiable.
The project also has a community governance layer backed by the A0T token on Ethereum BASE L2, letting token holders vote on feature priorities and development allocation. Venice AI integration gives community members access to private AI API keys at no cost.
Runs AI agents inside Trusted Execution Environments on NEAR AI Cloud, keeping credentials encrypted and invisible to the model at all times.
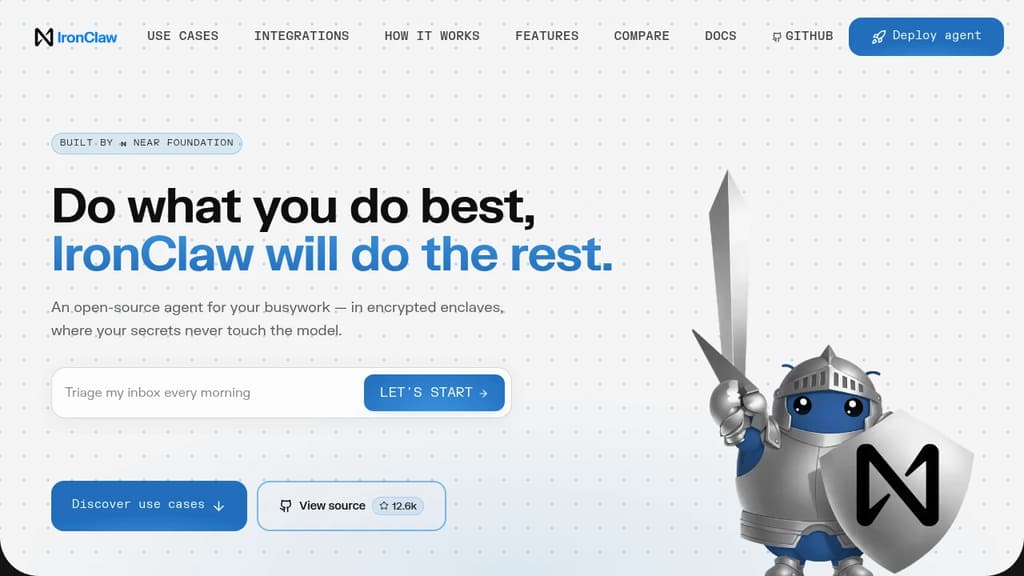
IronClaw is a secure AI agent runtime built for people who want to hand off real work to an AI agent without handing over their passwords, API keys, and tokens along with it. It runs on NEAR AI Cloud inside Trusted Execution Environments, meaning credentials are encrypted in memory from boot to shutdown. The AI model never sees the raw values.
The core problem it solves is real. Tools like OpenClaw give agents broad system access, but that access cuts both ways. A crafted prompt can trick the model into leaking every secret it holds. Malicious community skills have been found specifically designed to exfiltrate credentials. IronClaw's answer isn't a policy or a warning prompt; it's architecture.
Key security layers:
- Encrypted vault: Credentials are stored encrypted at rest and injected into outbound requests only at the host boundary, only for endpoints you've pre-approved.
- Per-tool Wasm sandboxes: Every skill runs in its own WebAssembly container with capability-based permissions. A compromised tool can't reach anything outside its sandbox.
- Network allowlisting: Tools can only contact endpoints you've explicitly approved. No silent phone-home, no unknown destinations.
- Real-time leak detection: Outbound traffic is scanned continuously. Anything resembling a secret heading out gets blocked before it leaves.
- Built in Rust: Memory safety is enforced at compile time. No garbage collector, no buffer overflows, no use-after-free vulnerabilities.
On the practical side, IronClaw handles the kind of recurring busywork that eats time. Inbox triage, daily briefings, meeting prep, deployment health checks, release tracking, invoice parsing, KPI reporting. It connects to Gmail, Google Calendar, Slack, Telegram, GitHub, Linear, Google Sheets, and anything else with an API. Missing an integration? It builds the connector itself from a plain-language description.
It's model-agnostic, compatible with Anthropic, OpenAI, Gemini, Mistral, Ollama, and several others. Deployment is one click on NEAR AI Cloud, with a free starter tier and paid plans scaling up to five concurrent agent instances.

People are looking for alternatives to...
View all alternatives
Claude Code
Spotify
CapCut

Claude
Notion
Lovable
 Sent – Messaging Infrastructure for Developers. One API for SMS, WhatsApp, and RCS across 190+ countries.

 Bright Data