Open Source LocalAI Alternatives
A curated collection of the 4 best open source alternatives to LocalAI.
The best open source alternative to LocalAI is Ollama. If that doesn't suit you, we've compiled a ranked list of other open source LocalAI alternatives to help you find a suitable replacement. Other interesting open source alternatives to LocalAI are: llama.cpp, vLLM, and GPT4All.
LocalAI alternatives are mainly Local Model Runners. Browse these if you want a narrower list of alternatives or looking for a specific functionality of LocalAI.

Written by Piotr Kulpinski
Runs open-source language models locally with a simple setup, plus optional cloud access for larger models when local hardware isn't enough.
Ollama lets you run large language models directly on your own hardware, without sending data to third-party APIs. It's built for developers, researchers, and anyone who wants the capabilities of modern AI models without giving up control over their data.
The core idea is local-first. Models run entirely on your machine, which means no usage fees per token, no data leaving your network, and full offline capability for sensitive or mission-critical work. When local hardware isn't enough, an optional cloud tier gives access to larger models running on datacenter-grade hardware.
Key capabilities:
- Local model execution runs models on your own CPU or GPU, keeping all data on-device
- Cloud scaling lets you access larger, faster models when local resources hit their limits, with servers in the US, Europe, and Singapore
- App and agent support connects with tools like Open WebUI and coding assistants, so you can build workflows around open models
- Parallel requests are supported in cloud mode, useful when running multiple agents or serving several users at once
- Web access is available for cloud models, giving them real-time information retrieval
- Data privacy guarantees mean your inputs are never used for training, on either local or cloud runs
Ollama fits naturally into setups where you want a local AI assistant or a self-hosted backend for agent-based tools. The free tier covers cloud model access at a basic level, with paid plans unlocking higher concurrency and usage limits for heavier workloads.
C/C++ inference engine for large language models, supporting quantization, multi-GPU, Apple Silicon, and an OpenAI-compatible server across a wide range of hardware.
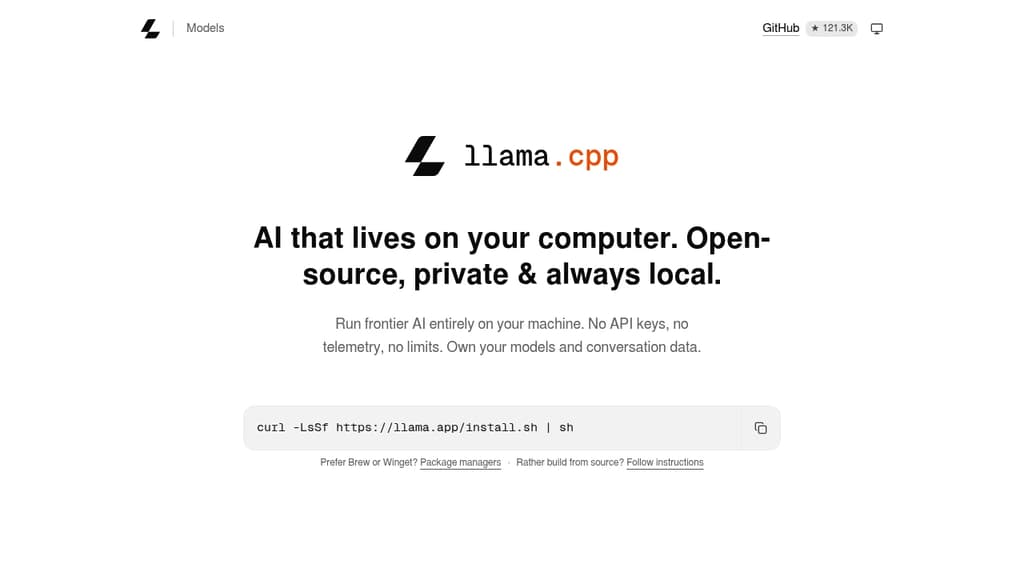
llama.cpp is a C/C++ inference engine for running large language models locally or in the cloud, with no external dependencies. It targets developers, researchers, and anyone who wants to run open-weight models on their own hardware without relying on cloud APIs.
The project's defining strength is hardware breadth. It runs on Apple Silicon via Metal and ARM NEON, NVIDIA GPUs via custom CUDA kernels, AMD GPUs via HIP, Intel hardware via SYCL, and a long list of other backends including Vulkan, Ascend NPU, and Snapdragon. CPU-only inference works too, and a hybrid CPU+GPU mode lets you run models larger than your available VRAM by splitting the load.
Quantization is a core feature. Models can be stored and run at 1.5-bit through 8-bit integer precision, dramatically reducing memory requirements while keeping inference fast. The GGUF format is the standard file format for these quantized models, and Hugging Face hosts a large library of compatible weights.
Key capabilities include:
- OpenAI-compatible HTTP server (
llama-server) with multi-user parallel decoding, speculative decoding, embedding endpoints, and reranking support - Grammar-constrained output for structured generation, including JSON, via custom GBNF grammars
- Multimodal support for vision-language models alongside dozens of text-only architectures including LLaMA 3, Mistral, Qwen, Gemma, Phi, DeepSeek, and many more
- Hugging Face integration for downloading models directly by name, with models stored in the standard HF cache so they're shareable with other tools
- Benchmarking and perplexity tools for evaluating model performance and quality
- Bindings for Python, Go, Rust, Node.js, Java, Swift, C#, and more than a dozen other languages
The server's OpenAI-compatible API makes it a drop-in backend for tools like AnythingLLM or observability platforms like Langfuse. A precompiled XCFramework is available for iOS, macOS, tvOS, and visionOS Swift projects.
llama.cpp is the reference implementation for GGUF and the ggml tensor library, making it the upstream project that much of the local LLM ecosystem builds on.
Inference and serving engine for large language models, built for speed and hardware efficiency with an OpenAI-compatible API and support for a wide range of open models.
vLLM is a serving engine for large language models, built for teams and developers who need to run LLMs at scale without burning through GPU budgets. It's designed around two core problems: throughput and memory. Most inference setups waste GPU memory and process requests inefficiently. vLLM addresses both.
The engine's standout technique is PagedAttention, which manages the KV cache the way an operating system manages virtual memory. This dramatically reduces memory waste and allows more requests to run concurrently on the same hardware. Paired with continuous batching, it keeps GPU utilization high even under variable load, rather than waiting to fill a fixed batch before processing.
Key capabilities include:
- OpenAI-compatible API so existing apps built against OpenAI's endpoints can switch to self-hosted models with minimal code changes
- Broad model support covering the latest open models, production-ready out of the box
- Multi-hardware support across NVIDIA, AMD, Intel, and CPU-only environments through a unified API
- Flexible deployment via Python package or Docker, with CUDA and ROCm builds available
For teams building on top of LLMs, vLLM fits naturally into LLM application frameworks and works alongside routing layers like LiteLLM or an LLM gateway for multi-provider setups. It's a common self-hosted alternative to managed inference services like Together AI.
Compared to tools like Ollama or llama.cpp, which prioritize ease of use on consumer hardware, vLLM targets production deployments where throughput per GPU matters. It's backed by compute resources from AWS, Google Cloud, NVIDIA, AMD, and others, and maintained by an active open-source community with support channels for both newcomers and teams running complex deployments.
GPT4All runs open-source language models locally on Windows, macOS, and Linux with no cloud dependency, keeping your data on your machine.
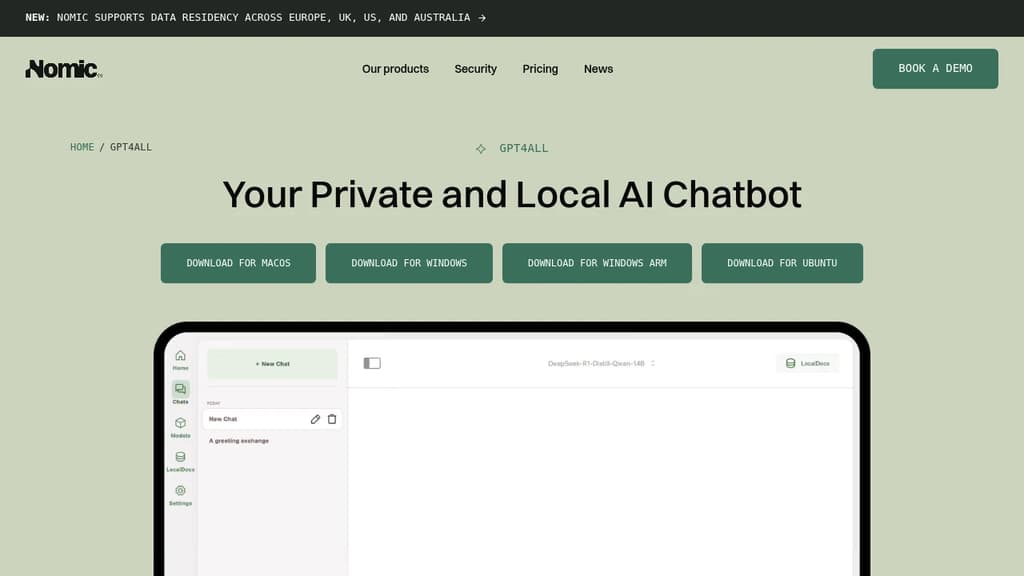
GPT4All is a desktop AI assistant that runs entirely on your own hardware. No cloud connection, no data leaving your machine. It's built for developers, teams, and power users who want the capabilities of a capable AI chatbot without handing their data to a third-party service.
It supports thousands of open-source models, so you're not locked into a single provider's offering. You can swap models depending on the task, your hardware, or your preference. That flexibility is rare among ChatGPT alternatives that run locally.
Key capabilities include:
- LocalDocs: Chat directly with your own documents. Point GPT4All at a folder of PDFs, text files, or other documents and ask questions against them without uploading anything.
- Cross-platform: Runs natively on Windows, macOS, and Linux.
- Model variety: Thousands of compatible open-source models, covering a wide range of sizes and specializations.
- Full customization: Build custom assistants and automate workflows using the local model stack.
- No internet required: Once a model is downloaded, everything runs offline.
For teams concerned about confidentiality, this is a meaningful distinction. Sensitive documents, internal processes, and proprietary data stay local. Tools like AnythingLLM and Open WebUI offer similar local-first approaches, but GPT4All's desktop client is one of the more accessible entry points, especially for non-technical users who still want control.
Performance depends on your hardware, but GPT4All is optimized to run efficiently on consumer-grade CPUs and GPUs. It doesn't demand a high-end workstation to be useful. The project is open source and maintained by Nomic AI, with an active model ecosystem and a growing community contributing compatible models.

People are looking for alternatives to...
View all alternatives
Claude Code
Spotify
CapCut

Claude
Notion
Lovable
 Docmost – Open-source wiki software with real-time collaboration, diagrams, AI, SSO, RBAC permissions and more.
 Sent