Dray vs Happy
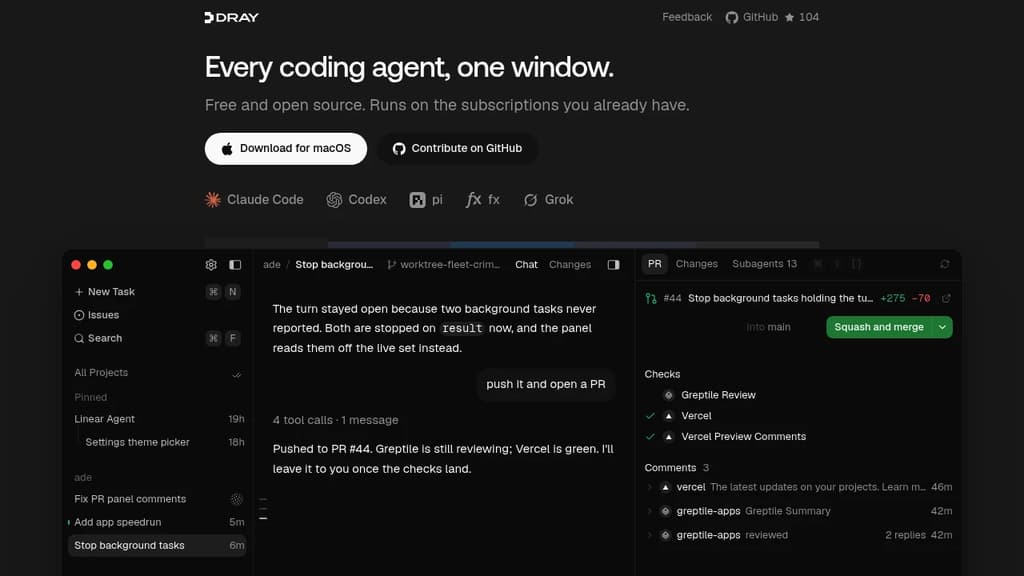
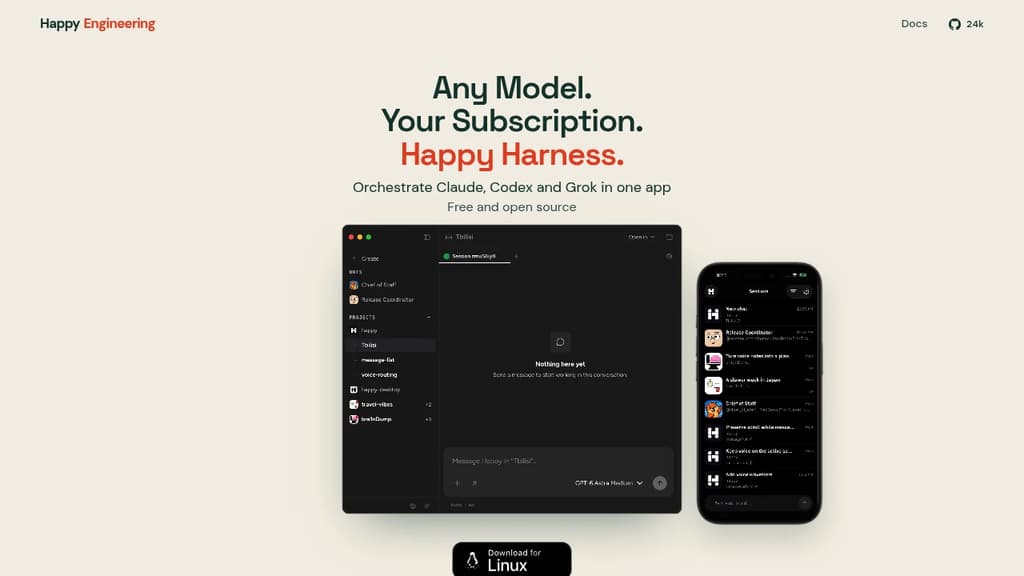
Learn how Dray and Happy differ in their key features, development activity, technology
stack and community adoption, so you can decide which of these ai coding agent orchestrators is best for you.
Learn how Dray and Happy differ in their key features, development activity, technology stack and community adoption, so you can decide which of these ai coding agent orchestrators is best for you.
Dray
Last 30 days
Last commit
2 days agoRepository age
3 monthsVersion
v0.29.7License
Apache-2.0Repository
monorepo-labs/dray
Happy
Last 30 days
Last commit
13 hours agoRepository age
1 yearVersion
1.2.5License
MITSelf-hosted
YesRepository
slopus/happy
Detailed Comparison
Happy appears to have several advantages over Dray, particularly in popularity, maturity, licensing and features. Consider your specific needs regarding popularity, growth, activity, maturity, licensing and features when making your decision.
Happy appears to have several advantages over Dray, particularly in popularity, maturity, licensing and features. Consider your specific needs regarding popularity, growth, activity, maturity, licensing and features when making your decision.
Community & Popularity
Happy significantly outpaces Dray in community adoption with 24,302 stars compared to 118 stars on GitHub. This 205.9x difference suggests Happy has a much larger and more active community. In terms of developer contributions, Happy has 2,083 forks, indicating strong developer engagement.
Growth Momentum
Dray is growing faster, adding 14 stars in the last 30 days (+13%) against adding 83 stars for Happy (+0.3%). Dray is the smaller project of the two, so it is closing the gap rather than extending a lead.
Development Activity
Both projects show recent activity, with Dray last updated 2 days ago and Happy 13 hours ago.
Project Maturity
Happy has been in development longer, starting 1 year ago, compared to Dray which began 3 months ago. This 1.0-year head start suggests Happy may have more mature features and established processes.
Licensing
Happy uses the MIT license, which is more permissive than Dray's Apache-2.0 license, potentially offering greater flexibility for commercial use and integration.
Use Cases & Features
Both tools serve similar use cases in AI Coding Agent Orchestrators.
Hosting & Deployment
Happy provides self-hosting options for complete data control and customization, while Dray may be primarily cloud-based or require different deployment approaches.

 Sent – A unified API for sending messages across SMS, RCS, and apps like WhatsApp.