Open Source Bright Data Alternatives
A curated collection of the 5 best open source alternatives to Bright Data.
The best open source alternative to Bright Data is Firecrawl. If that doesn't suit you, we've compiled a ranked list of other open source Bright Data alternatives to help you find a suitable replacement. Other interesting open source alternatives to Bright Data are: Crawl4AI, Lightpanda, Maxun, and OpenSERP.
Bright Data alternatives are mainly Scraping Platforms & SDKs but may also be Web Crawlers or Browser Automation for AI Tools. Browse these if you want a narrower list of alternatives or looking for a specific functionality of Bright Data.

Written by Piotr Kulpinski

API for AI agents to search, scrape, crawl, and interact with the live web, returning clean Markdown, structured JSON, or screenshots from any page.
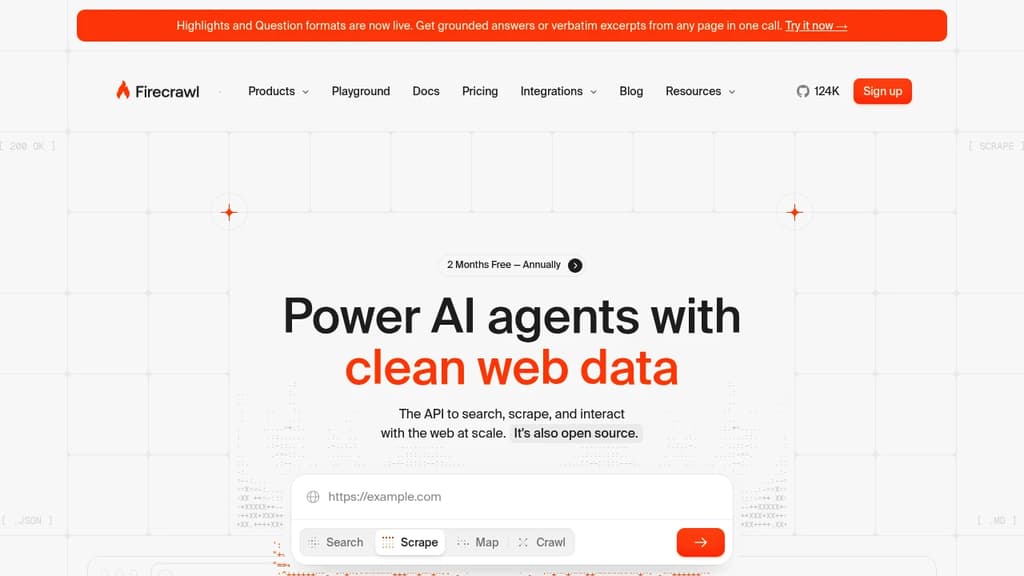
Firecrawl is a web data API built specifically for AI systems. It takes the messy, JavaScript-heavy, human-oriented web and converts it into structured data that agents and LLM pipelines can actually use. Over 80,000 companies rely on it, from indie developers wiring up AI search tools to teams at Apple and Canva running production-scale pipelines.
The three core capabilities work together:
- Search returns full-page Markdown alongside results, so one call goes from a query to usable content without a separate scrape step.
- Scrape handles JavaScript rendering, smart waits, and dynamic content automatically. Pass a URL and get back Markdown, HTML, screenshots, metadata, or structured JSON via a schema you define.
- Interact goes further. It lets agents click, scroll, type, and navigate multi-step flows, reaching data behind logins, pagination, or any sequence of actions a static scrape can't touch.
For browser automation for AI use cases, Firecrawl connects directly to MCP-compatible clients like Cursor, Claude, and Windsurf. There's also a CLI and official SDKs for Python, Node.js, Go, Rust, Java, and Elixir.
Under the hood, it covers 96% of the web with a reported P95 latency of 3.4 seconds across millions of pages. The hosted version adds proprietary infrastructure for proxy management and rendering reliability. The self-hostable version is the largest open source repo in the web crawlers space, with over 100,000 GitHub stars.
Common use cases include deep research agents, RAG pipelines, lead enrichment, competitive intelligence, and price monitoring. The free tier covers 1,000 pages per month, with paid plans scaling to millions of pages for larger workloads.
Unlike scraping tools that stop at raw HTML, Firecrawl parses PDFs and DOCX files, extracts structured data against a JSON schema, and caches results against a growing web index. It's a practical fit for any AI workflow that needs reliable, clean input from the live web.
Open-source web crawler and scraper that produces clean, structured output optimized for LLMs, RAG pipelines, and AI agents. Supports async crawling, CSS/XPath/LLM extraction, and stealth browser control.
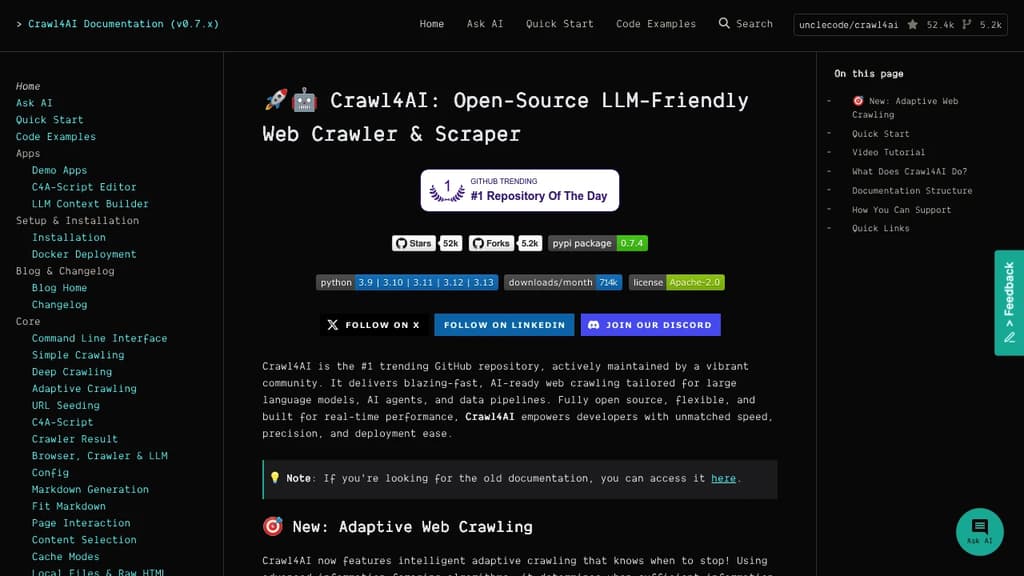
Crawl4AI is a web crawler and scraper built specifically for feeding data into AI pipelines and agents. Where generic scrapers dump raw HTML, Crawl4AI outputs clean Markdown and structured data that LLMs can consume directly, without heavy post-processing.
It's aimed at developers building RAG systems, data pipelines, or AI agents that need reliable, well-formatted web content at scale. The async-first architecture means you can run parallel crawls without blocking, making it practical for real-time use cases.
Key capabilities include:
- Clean Markdown output formatted for direct ingestion into LLMs or AI search tools, with minimal noise
- Structured extraction using CSS selectors, XPath, or LLM-based strategies for pulling repeated patterns from pages
- Adaptive crawling that uses information foraging algorithms to stop once enough data has been gathered to answer a query
- Advanced browser control including hooks, proxies, stealth modes, and session reuse for handling JavaScript-heavy or auth-protected sites
- Chunking and clustering approaches for breaking large pages into digestible pieces before passing to models
- No forced API keys or paywalls – you own the extraction process end to end
Compared to alternatives like Firecrawl or Jina AI, Crawl4AI leans heavily on self-hosting and configurability. You're not routing traffic through a third-party service, and there's no usage metering on the open-source version.
It also ships an AI assistant skill package (compatible with Claude, Cursor, and similar AI coding assistants) that bundles the full SDK reference and ready-to-use extraction scripts, so you can query the docs from inside your editor.
Deployable via pip or Docker, with a Python async API that fits naturally into existing data engineering workflows.
Purpose-built headless browser that delivers 10x faster performance and 10x lower memory usage compared to Chrome headless for web automation and AI workflows.
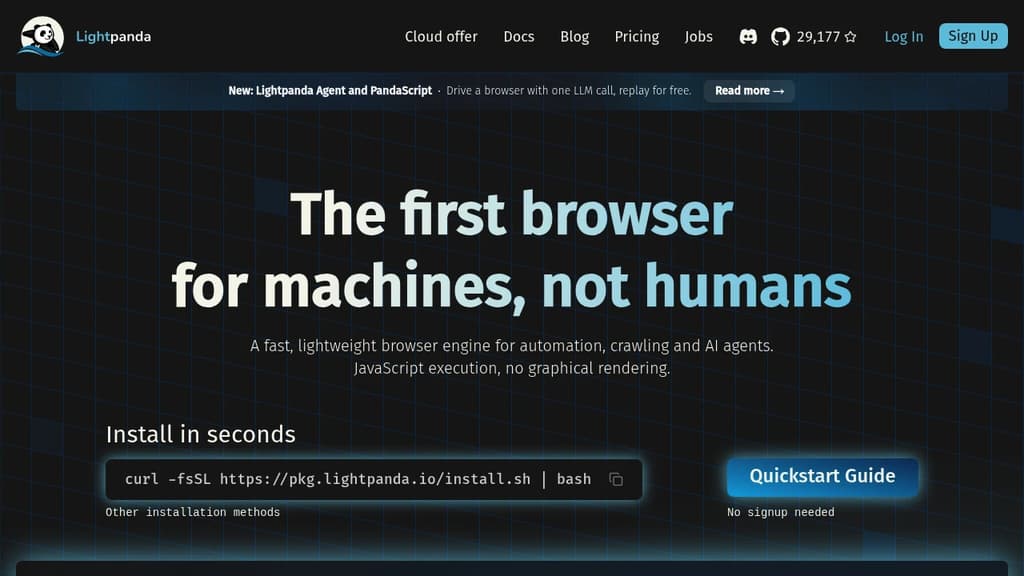
Lightpanda is a groundbreaking headless browser built from scratch specifically for machines and automation. Unlike other solutions that modify existing browsers, Lightpanda was developed from the ground up in Zig, a low-level programming language optimized for performance.
Key benefits include:
- Superior Performance: 11x faster execution time and 9x lower memory usage compared to Chrome headless
- AI-Native Design: Purpose-built for AI agents and automation workflows with instant startup
- Efficient Scraping: Handles resource-intensive web scraping with minimal CPU and memory footprint
- Full Compatibility: Works with existing tools like Puppeteer and Playwright
- Easy Integration: Simple drop-in replacement for Chrome headless in existing code
The browser's focused architecture eliminates unnecessary rendering overhead while maintaining full web standards compatibility. This makes it ideal for high-volume automation, web scraping, and AI agent applications where performance and resource efficiency are critical.
Turn any website into structured data using a visual recorder, natural language prompts, or API. Includes proxy rotation, scheduling, and webhook integrations.
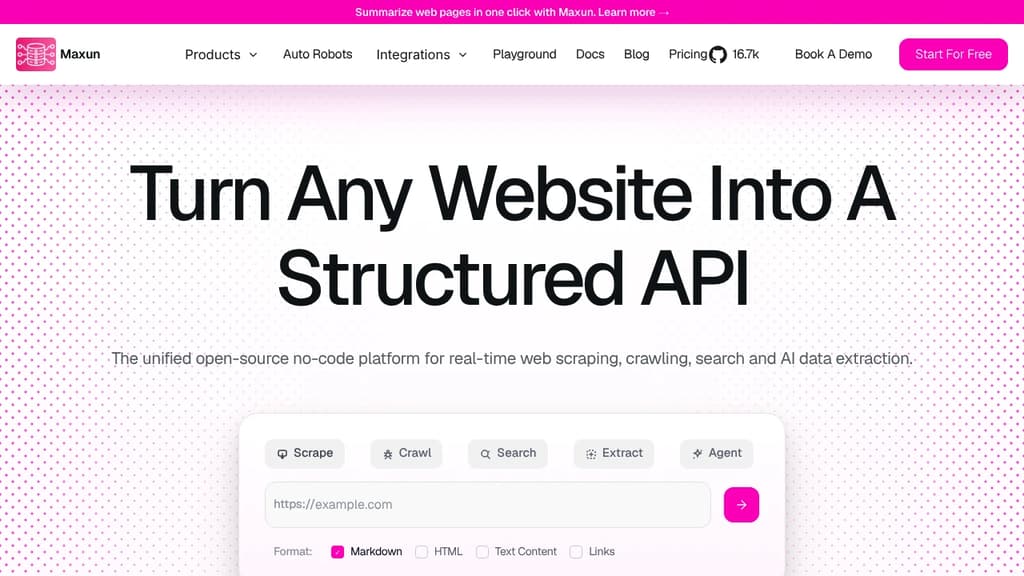
Maxun is a no-code platform for scraping, crawling, and extracting data from websites. It's built for developers and non-technical users alike who need structured data from the web without writing custom scrapers or maintaining brittle pipelines.
The core idea is simple: record your actions in a browser, and Maxun turns that recording into a reusable "robot" that extracts data on demand. No selectors to write, no code to maintain. You can also skip the recorder entirely and describe what you want in plain language. The AI agent navigates the site and pulls the relevant data automatically.
Key capabilities:
- Visual recorder builds production-ready scrapers by watching you browse, capturing clicks and scrolls into a repeatable workflow
- Natural language extraction lets you describe the data you need; the agent figures out how to get it
- Full-site crawling maps and extracts content across entire domains, not just single pages
- Web search finds relevant pages matching a query before extraction
- Scheduled monitoring runs scrapers hourly or daily to track price changes, job listings, or any content that updates
- Stealth mode handles proxy rotation and browser fingerprinting so scrapers don't get blocked
- Multiple output formats including Markdown, HTML, raw text, and links, ready for LLM pipelines or downstream apps
For developers who want more control, Maxun exposes a REST API, Python and JavaScript SDKs, a CLI, and native MCP support for agent orchestration. It fits naturally into workflows where an AI agent needs to call a web scraping tool as a skill. There are also pre-built robots for common targets like GitHub trending repos, IMDb, YouTube, and Airbnb listings.
Compared to tools like Firecrawl or Crawl4AI, Maxun leans harder into the no-code recorder experience and autonomous agents, making it accessible to people who don't want to touch an API at all. It's a self-hostable alternative to proprietary platforms like Apify or Octoparse, with the full codebase available on GitHub.
Over 100 million rows have been extracted through the platform, and it carries more than 14,000 GitHub stars.
Query Google, Bing, Yandex, Baidu, DuckDuckGo, and Ecosia through one REST API. Self-host free under MIT, or use the managed cloud option.
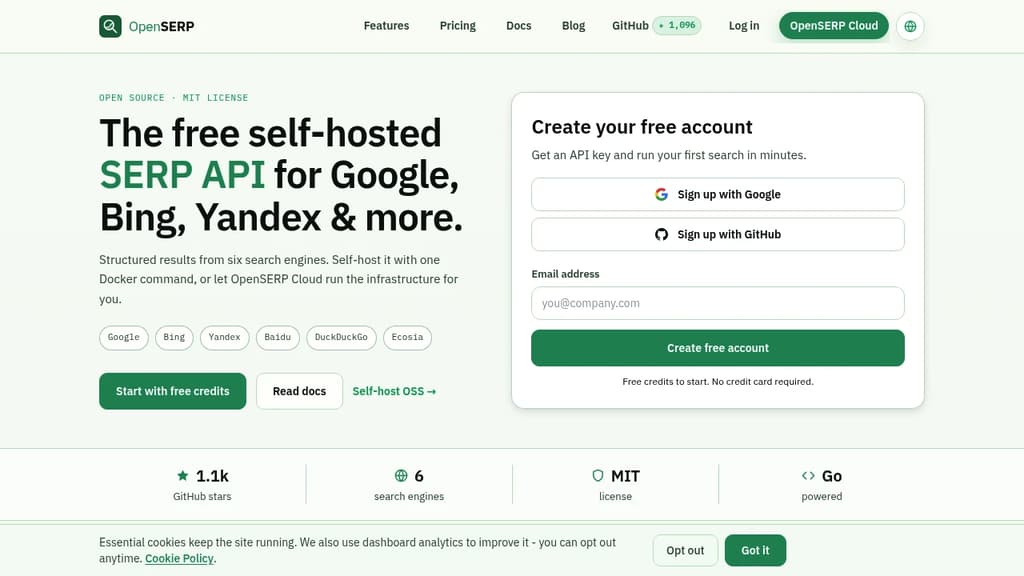
OpenSERP is a self-hosted REST API that pulls structured search results from six major search engines through a single, consistent endpoint. It's built for developers, SEO teams, and AI pipelines that need programmatic access to live SERP data without paying per-query fees or accepting vendor lock-in.
The self-hosted version is completely free. No API keys, no rate limits beyond your own hardware, no subscription. One Docker command starts a local server you can query immediately from any app, script, or pipeline.
What it returns is consistent JSON across every engine: titles, URLs, snippets, rank positions, and SERP features including AI summaries, answer boxes, people-also-ask, and related searches. Output can also be requested as Markdown, plain text, or NDJSON.
Key capabilities:
- Six engines supported: Google, Bing, Yandex, Baidu, DuckDuckGo, and Ecosia for web and image search
- Uniform response shape: the same JSON envelope regardless of which engine you query, so switching or combining engines requires no extra parsing logic
- SERP feature extraction: captures AI summaries, answer boxes, and related searches alongside organic results
- MIT license: full source on GitHub, deploy on any infrastructure you already run
- Multi-engine megasearch: the managed Cloud tier adds endpoints that query several engines in a single call
Common use cases include SEO rank tracking across regional engines like Yandex and Baidu, grounding LLM responses with live search data, feeding Firecrawl-style scraping pipelines, and competitor monitoring. It's a direct open-source alternative to paid providers like DataForSEO.
For teams that don't want to manage infrastructure, OpenSERP Cloud offers the same API as a managed endpoint with free starter credits and pay-as-you-go pricing. The open-source version and the cloud path share the same underlying codebase.

People are looking for alternatives to...
View all alternatives
Spotify

Claude
Claude Code
CapCut
Lovable
Amazon Prime
 Postiz – The All-in-One agentic social media scheduling tool
 Windshift