Open Source Apache Druid Alternatives
A curated collection of the 2 best open source alternatives to Apache Druid.
The best open source alternative to Apache Druid is InfluxDB. If that doesn't suit you, we've compiled a ranked list of other open source Apache Druid alternatives to help you find a suitable replacement. Other interesting open source alternative to Apache Druid is TimescaleDb.
Apache Druid alternatives are mainly Time Series Databases but may also be Relational Databases (SQL). Browse these if you want a narrower list of alternatives or looking for a specific functionality of Apache Druid.

Written by Piotr Kulpinski
InfluxDB handles high-velocity, high-resolution time series data at scale, built for telemetry, edge devices, IoT, and physical AI workloads.
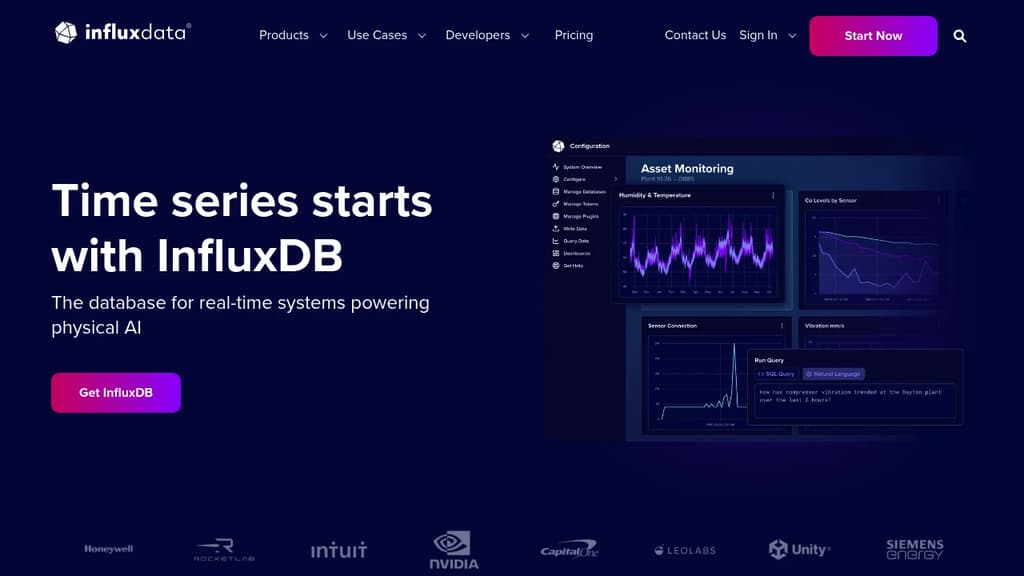
InfluxDB is a time series database built specifically for systems that generate continuous, high-resolution data. Think industrial sensors, satellite telemetry, power grids, and infrastructure monitoring. General-purpose databases weren't designed for this kind of workload, and the performance difference shows at scale.
The core strength is ingest speed. InfluxDB handles millions of data points per second without sacrificing query latency or blowing up storage costs. It uses efficient compression and stores data in Parquet format, which keeps footprint manageable even over long retention windows. Cold data gets automatically evicted and streamed into data lakes, warehouses, or AI/ML pipelines, so you're not paying hot-storage prices for data you rarely touch.
Key capabilities include:
- High-speed ingest – Millions of series ingested continuously without performance degradation
- Real-time analytics – SQL-based querying across unlimited series with low latency
- Edge-to-cloud continuity – Capture data at the source and analyze it anywhere without pipeline redesign
- Lakehouse integration – Automatic eviction of cold data into lakes, warehouses, and AI/ML systems
- 400+ Telegraf plugins – The open source Telegraf agent connects InfluxDB to virtually any data source, with over 5 billion downloads
- Client libraries – Official support for Python, Go, JavaScript, Java, and C#
Deployment is flexible. You can run it self-managed on-prem or at the edge, or use the fully managed cloud offering. Both options share the same engine, so you're not locked into a single environment.
Compared to alternatives like QuestDB, TDengine, or Timescale, InfluxDB has the largest installed base in its category, with over 1 million live open source instances and more than 2,800 contributors. It's ranked the top time series database by DB-Engines.
The tool targets engineers building monitoring systems, physical AI pipelines, aerospace telemetry platforms, and industrial data historians. If your workload involves continuous sensor streams and you need both fast writes and fast reads, InfluxDB is built around exactly that problem.
PostgreSQL extension for time-series data with automatic partitioning, up to 95% columnar compression, continuous aggregates, and ~200 native SQL functions.
TimescaleDB is a PostgreSQL extension that turns Postgres into a purpose-built time-series database. It's designed for teams that want specialized time-series performance without abandoning the SQL ecosystem they already know. Sensor data, on-chain events, application metrics, customer behavior – if it's timestamped and high-volume, this is what it's built for.
The core abstraction is the hypertable: a regular Postgres table that's automatically partitioned by time (or ID) under the hood. Partition skipping at query planning means the database eliminates irrelevant chunks before scanning begins, so queries stay fast even as data grows into billions of rows.
Key capabilities:
- Hybrid row/columnar storage – recent data stays in the rowstore for fast ingest and point lookups; older data auto-converts to columnar format for analytical scans, with SIMD-accelerated vectorized execution
- Compression up to 95% – delta, dictionary, and RLE encodings compress historical data aggressively, and queries can filter directly on compressed data without decompressing first
- Continuous aggregates – incrementally refreshed materialized views that update in parallel batches; real-time mode includes the latest uncommitted data so dashboards never go stale
- ~200 time-series SQL functions – hyperfunctions cover time-weighted averages, interpolation, gap-filling, and partial aggregations that avoid reprocessing historical data
- Automated data management – built-in job scheduler handles retention policies, columnstore conversion, and aggregate refresh with configurable retries and full auditability
Because it's 100% PostgreSQL-compatible, existing Postgres tooling, drivers, ORMs, and extensions all work without modification. That's a meaningful difference from purpose-built alternatives like InfluxDB, QuestDB, or TDengine, which require learning new query languages or migration overhead.
Cloudflare uses it to balance analytical performance with operational simplicity, keeping analytical and configuration data under one roof. The project has 22,000+ GitHub stars and an active Slack community of 12,000+ members.

People are looking for alternatives to...
View all alternatives
Claude Code
Spotify
Notion
CapCut
Lovable
Wispr Flow
 ScreenshotOne – The screenshot API for developers. Render screenshots in one simple API call
 Sent